arXiv Preprint Introduces ResOT for Mitigating Object Hallucination in LVLMs
The October 8 2026 arXiv preprint presents ResOT, a training-free inference-time approach using localized distribution alignment via Gaussian optimal transport to repair…
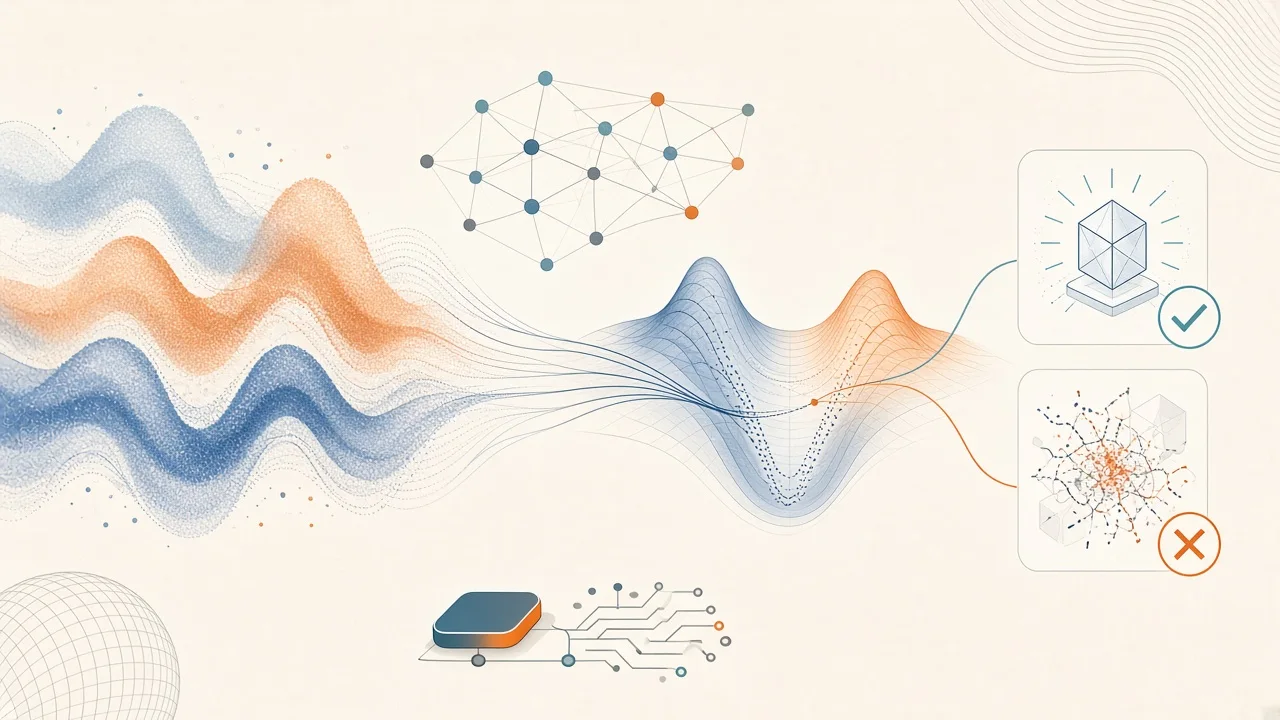
- ResOT forms a residual subspace and applies Gaussian optimal transport to align distributions, producing repair targets with minimal changes to original representations.
- Abstract reports substantial reduction in object hallucination on three LVLMs alongside improved image caption quality and multimodal benchmark performance.
- As a training-free inference method, it offers potential applicability to existing models without retraining, though full implementation details await the paper and code release.
Object Hallucination in Vision-Language Models
Object hallucination, where models describe objects absent from input images, continues to limit reliability of large vision-language models. Suppressing suspected hallucination-related components in hidden states can inadvertently remove useful information, harming overall multimodal performance.
This report is based solely on the abstract of the October 8 2026 arXiv preprint. The full paper is not available here, and no independent replication has been conducted.
ResOT Method Overview
The preprint proposes ResOT, which projects dominant hallucinated directions to isolate a low-dimensional residual subspace. Gaussian optimal transport is then used within this subspace to align the hallucinated distribution with the faithful one.
This produces repair targets requiring only small modifications to token states. During inference the method adaptively controls movement of each token representation toward its target.
Experimental Results
According to the abstract, experiments on three representative LVLMs demonstrate that ResOT reduces object hallucination while improving image caption quality and performance on multiple multimodal benchmarks.
The authors state that code will be released.
Significance for Model Reliability
Training-free techniques operating at inference time, such as the one described, could help users enhance truthfulness in vision-language outputs without model retraining. This preprint underscores ongoing research into representation-level interventions that balance faithfulness and capability preservation.
Our editorial stance supports user choice in open models and lawful expression, allowing individuals to select tools that best align with their needs for reliable AI generation rather than relying solely on corporate gatekeepers.