arXiv Preprint Proposes Layer-Informed Fine-Tuning for LLMs
A September 2026 arXiv preprint hypothesizes that LLM layers divide labor across conceptualization, reasoning and textualization stages and introduces Layer-Informed…
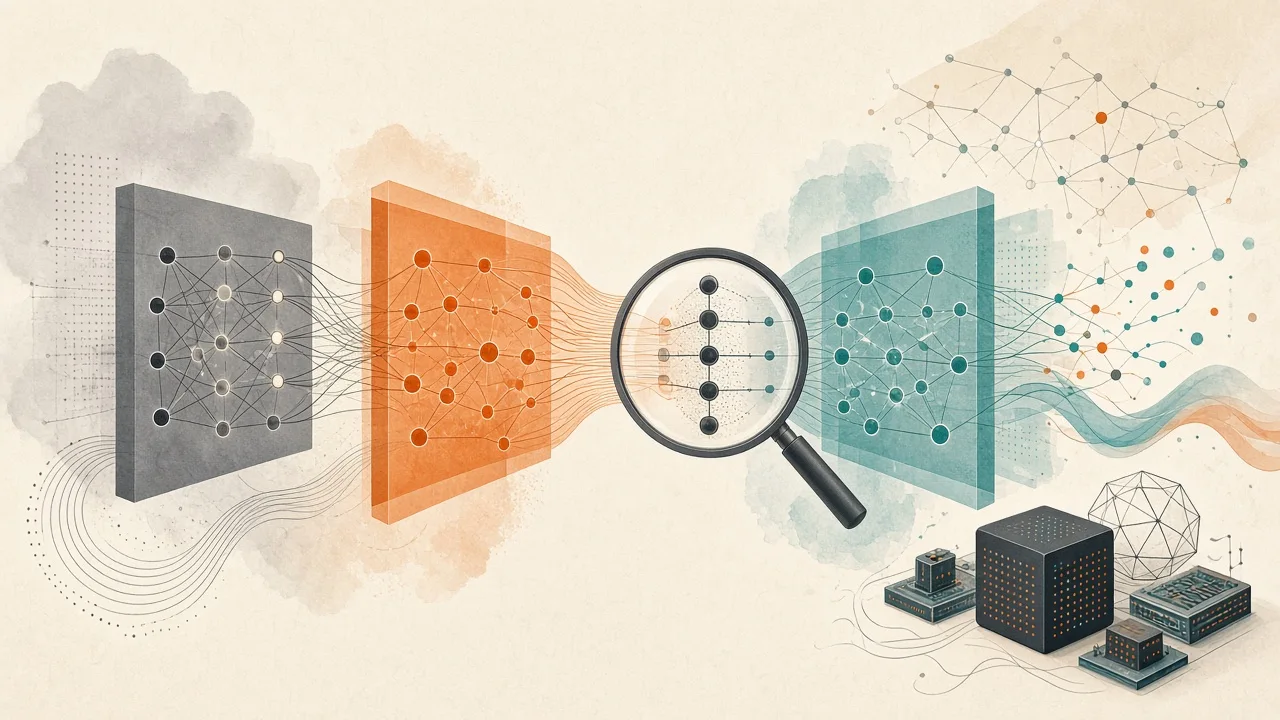
- The preprint hypothesizes a three-stage functional division of labor in LLM layers when handling cross-linguistic reasoning tasks.
- A sensitivity-analysis mechanism is proposed to identify task-specific functional bottlenecks before fine-tuning.
- The resulting Layer-Informed Fine-Tuning approach is claimed in the abstract to accelerate training while improving performance.
Three-Stage Functional Hypothesis
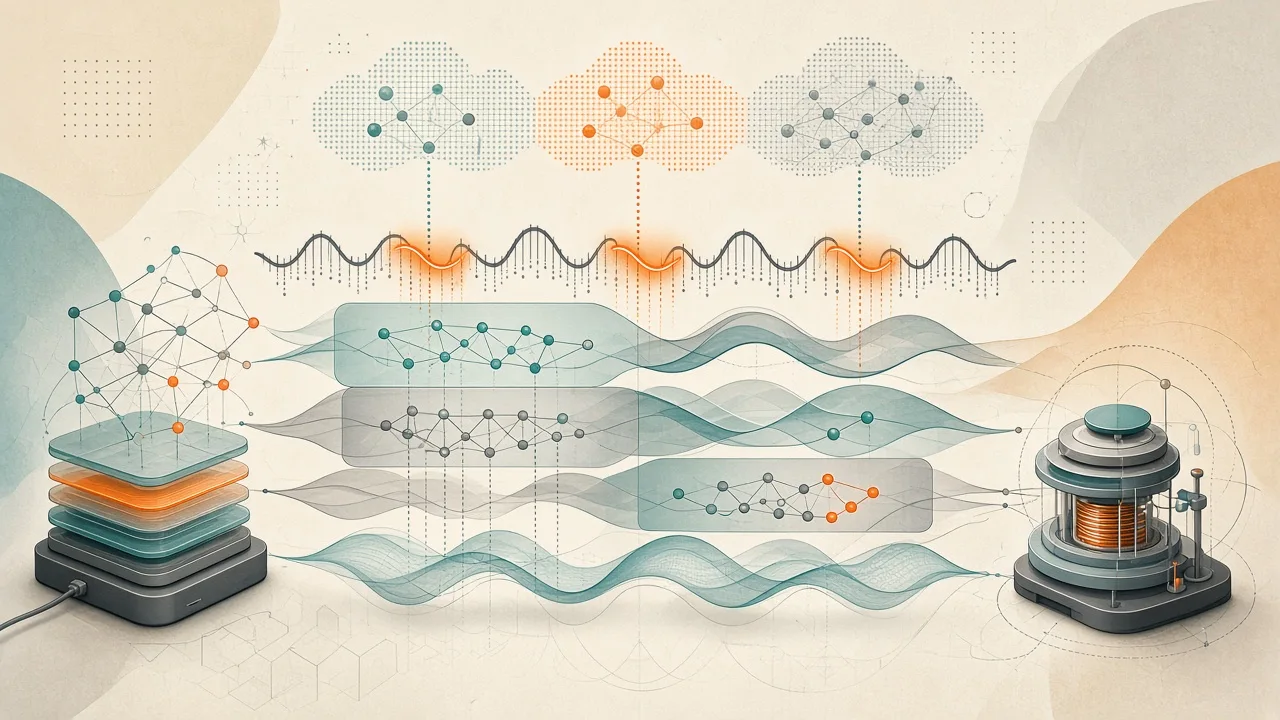
The preprint hypothesizes that LLM layers exhibit a structured division of labor across conceptualization, reasoning and textualization when processing cross-linguistic materials.
This perspective seeks to improve understanding of how model structure and internal parameters progressively solve complex reasoning problems.
All claims are drawn from the supplied abstract only; the full paper is not available and no independent replication has been performed.
Bottleneck Identification Mechanism
The authors describe a sensitivity-analysis technique that locates the most critical functional stage for a given task.
This diagnostic step is intended to pinpoint bottlenecks so that adaptation effort can focus on functionally important layers.
The abstract positions the mechanism as a way to avoid updating every parameter during fine-tuning.
Layer-Informed Fine-Tuning Approach
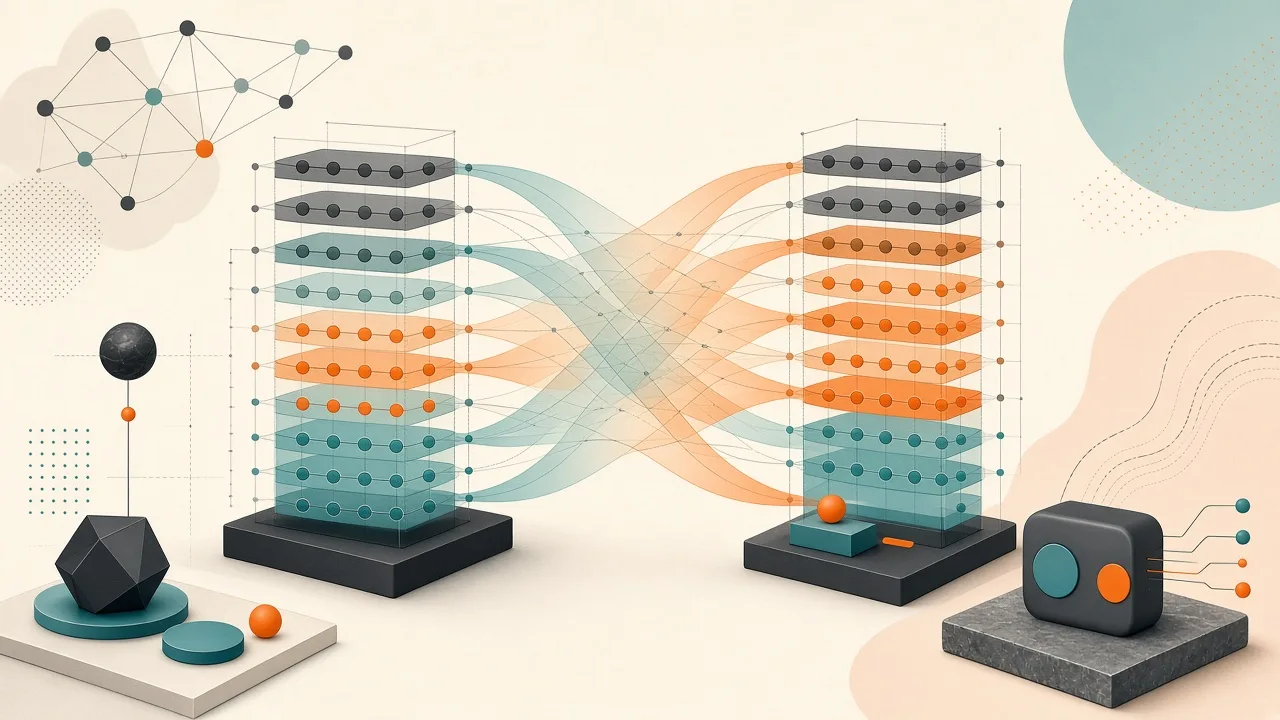
Layer-Informed Fine-Tuning, abbreviated LIFT, selectively updates only the layers identified as critical for the task.
According to the abstract, this targeted strategy both speeds up the training process and yields better model performance than standard full-model fine-tuning.
The preprint remains at the abstract stage; detailed experimental settings, exact results and code are not yet public.
Implications for Efficient Model Adaptation
Methods that reveal layer-level functional roles can help practitioners reduce compute costs when customizing open-weight models for specialized reasoning.
Targeted updates may lower hardware barriers for users running models locally while still aiming to enhance output quality on demanding tasks.
The preprint offers an early conceptual contribution; further validation will be needed once the full paper appears.