MultiAlloc: Profiling-Guided Precision Allocation for KV Cache Quantization
This arXiv preprint presents MultiAlloc, a framework that uses offline profiling of layer sensitivity and token importance to allocate limited quantization resources between…
- MultiAlloc derives an effective precision allocation policy from lightweight offline profiling without requiring online search during inference.
- It improves performance over prior layer-wise, token-wise, and multi-granularity KV cache quantization methods on matched memory budgets.
- Evaluations cover reasoning and long-context benchmarks across models including Mistral, Llama, DeepSeek-Qwen, and QwQ.
The KV cache memory challenge in LLM inference
The Key-Value cache represents a dominant source of memory consumption during large language model inference, especially in long-context and complex reasoning scenarios.
Prior quantization approaches have examined different compression granularities such as layer-wise precision adjustment and token-level information preservation.
The practical deployment issue centers on how to distribute limited quantization resources across these heterogeneous strategies while respecting a fixed memory budget.
How MultiAlloc works
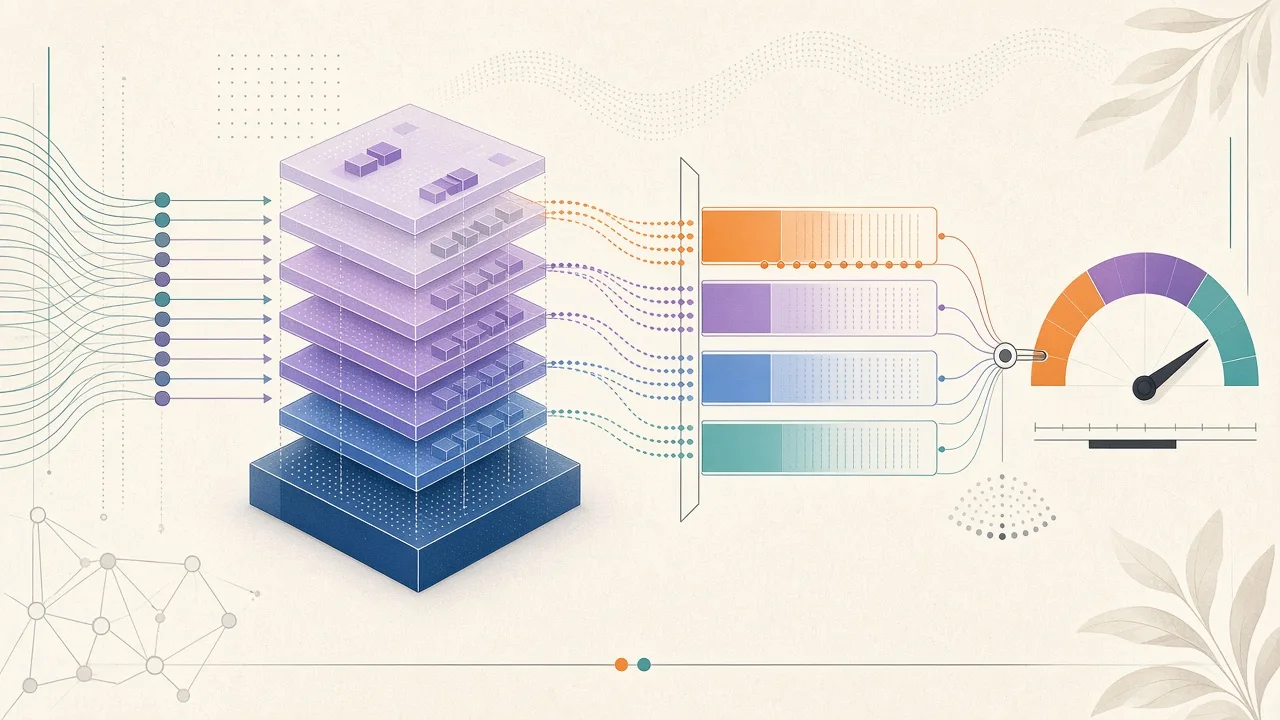
MultiAlloc is a profiling-guided precision allocation framework that adaptively assigns resources between layer-wise precision enhancement and token-wise preservation.
It conducts lightweight offline profiling to characterize layer sensitivity and token importance, then uses the observed memory-accuracy trade-off to automatically determine an allocation strategy.
The resulting policy is applied at inference time, eliminating the need for costly online allocation search.
Experimental results
Experiments on reasoning and long-context benchmarks indicate that MultiAlloc consistently outperforms existing layer-wise, token-wise, and recent multi-granularity KV cache quantization methods when memory budgets are matched.
The tested models include Mistral, Llama, DeepSeek-Qwen, and QwQ.
This capture is limited to the arXiv abstract dated October 13 2026; the full paper is required for complete methodological details, quantitative metrics, and reproducibility.