Q-PACE Preprint Proposes Dynamic Precision Allocation for Quantization-Aware Training
arXiv preprint dated 2026-10-06 introduces Q-PACE, a second-order sensitivity model using per-layer curvature coefficients to dynamically assign mixed precision during QAT…
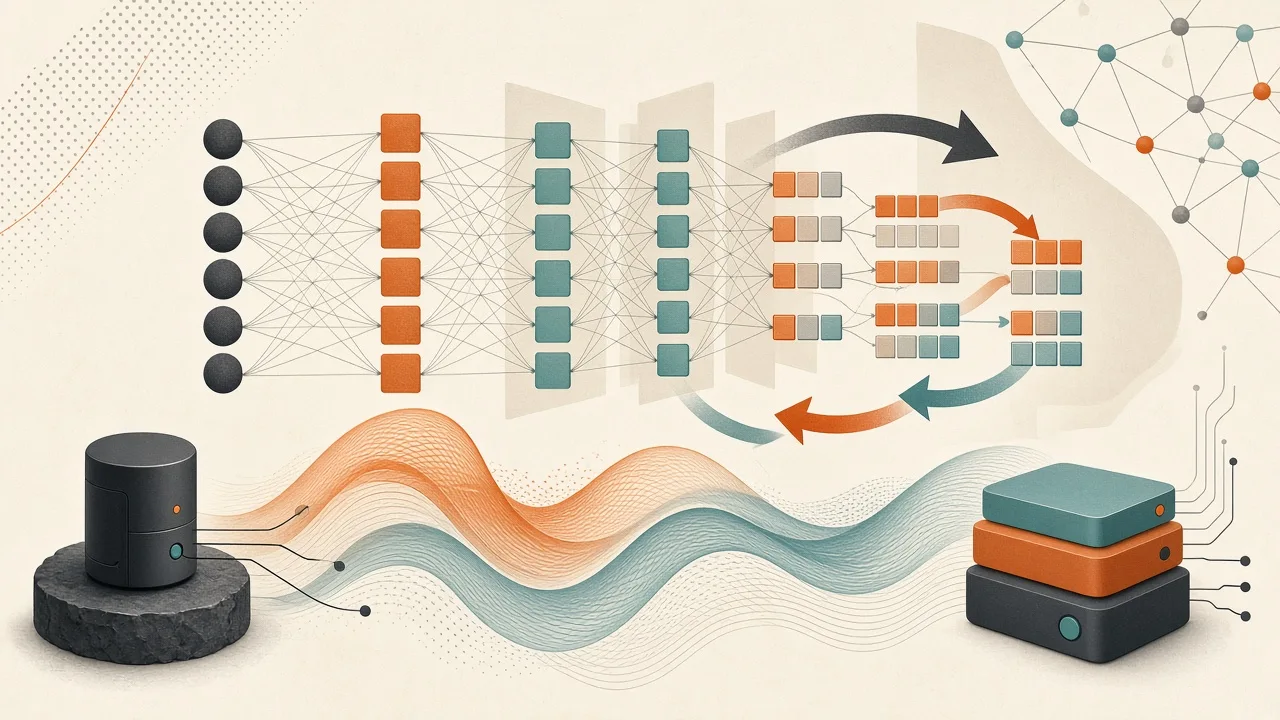
- Q-PACE periodically recomputes curvature coefficients with layer perturbations and reassigns precision to balance performance and memory.
- Quantization sensitivity is predictable by layer depth and type and remains stable, supporting infrequent recalibration.
- The abstract reports lower memory budgets with comparable loss versus prior mixed-precision methods; full paper verification is required.
Core Method in the Preprint
The abstract describes Q-PACE as modeling expected loss increase from quantization as a sum of per-layer quantization noise mean-squared-error terms weighted by curvature coefficients obtained from a second-order sensitivity approach.
During training the curvature coefficients are recomputed at intervals using perturbations applied across layers, after which precision assignments for each layer are updated.
Experiments on pretraining and supervised fine-tuning of LLMs up to 4B parameters indicate that the method achieves comparable loss at substantially lower total memory budgets than existing mixed-precision training approaches.
Observed Sensitivity Patterns
The authors observe that quantization sensitivity correlates strongly with layer depth and type.
This predictability and the stability of sensitivity during training allow recalibration to be performed infrequently and at low computational cost.
Evidence Basis and Limitations
This report is based exclusively on the arXiv abstract dated 2026-10-06; the full paper has not been reviewed and no independent replication is available.
All claims of consistent improvement, memory savings, and sensitivity patterns are those of the preprint authors and remain unverified beyond the supplied summary.
Details such as exact recomputation frequency, perturbation magnitude, and quantitative sensitivity metrics are not present in the abstract.
Practical Considerations for Adoption
Practitioners interested in mixed-precision quantization-aware training may evaluate whether the dynamic allocation strategy reduces memory pressure in their workflows once the full paper and any accompanying code are released.
The reported stability of sensitivity patterns suggests that even simpler static schedules informed by depth and layer type could offer efficiency gains without continuous recomputation.