Preprint Explains Why Safety-Aligned LLMs Over-Refuse Harmless Queries
An October 29 2026 arXiv preprint shows that in safety-trained models harmful and over-refusal sample representations overlap in deeper layers while harmful gradients bias…
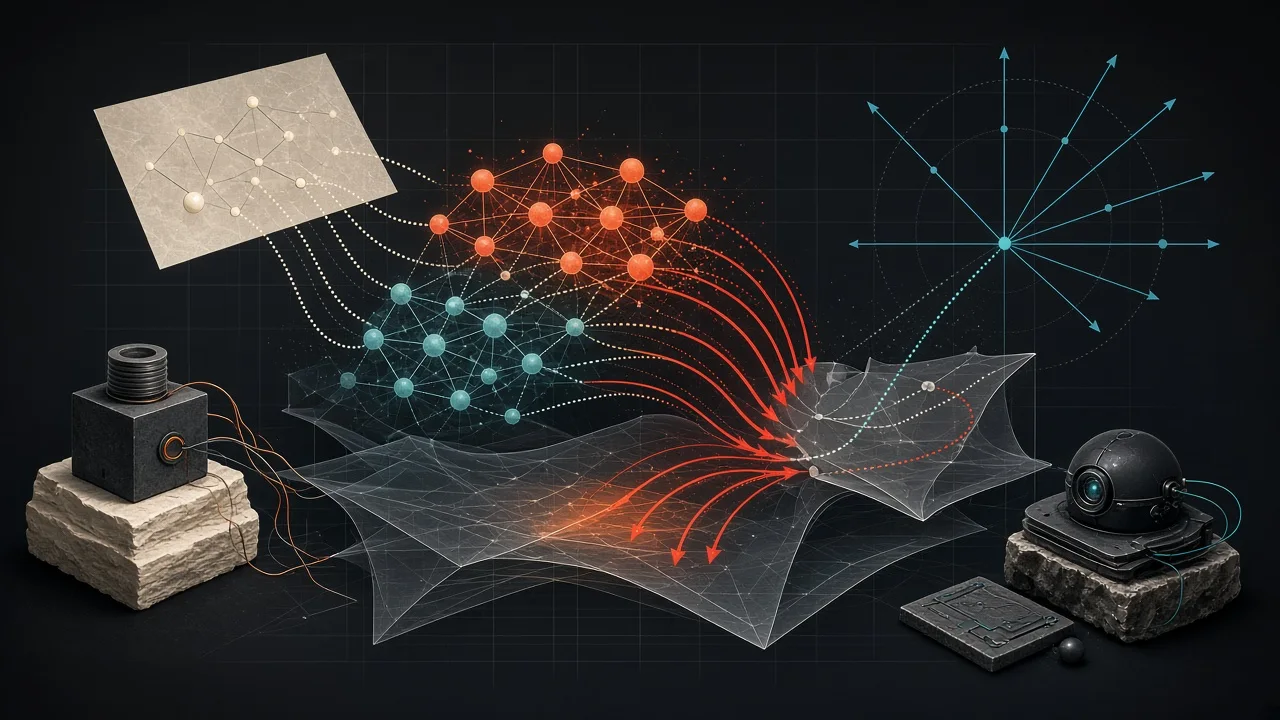
- Representations of harmful and harmless-but-risky prompts are distinct in middle layers but overlap deeper in the model.
- Harmful gradients concentrate in a low-rank subspace and align more with refusal than with helpful responses on over-refusal examples.
- GOAL uses gradient orthogonalization and contrastive learning to cut over-refusal while preserving safety and general performance.
What the preprint found
Safety alignment often causes large language models to reject harmless queries that merely appear risky, a problem called over-refusal. This arXiv preprint, whose abstract was released October 29 2026, examines the issue from a representation and optimization viewpoint using only the supplied abstract.
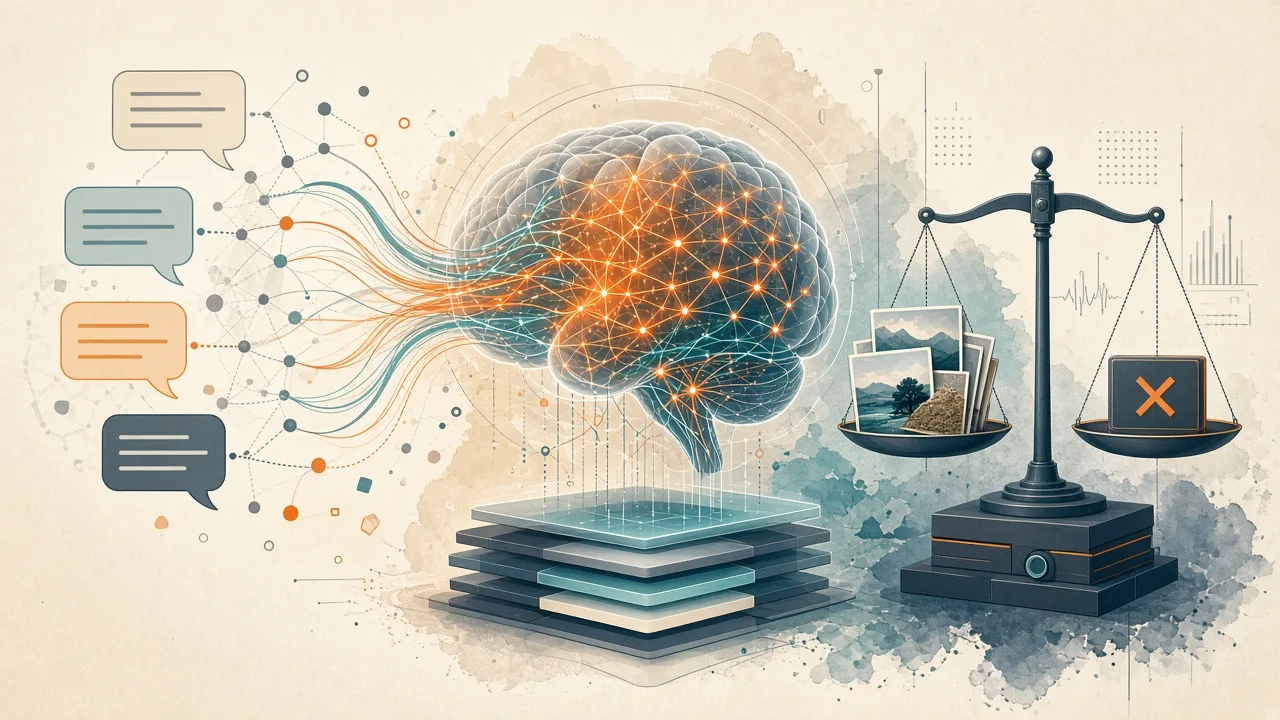
The authors report two observations. First, internal representations of clearly harmful prompts and over-refused harmless ones are visually distinguishable at certain intermediate layers but increasingly overlap in deeper layers. Second, gradients from harmful samples show high intra-class similarity, concentrate in a low-rank subspace, and align more strongly with refusal-target gradients than with helpful-target gradients on over-refusal prompts.
According to the abstract this imbalanced gradient coupling biases over-refusal samples toward refusal, while the reduced representational separation in deeper layers makes it harder for the model to maintain a clear boundary between harmful and harmless cases.
The proposed GOAL method
To address these dynamics the researchers introduce GOAL, short for Gradient Orthogonalization with contrAstive Learning. It has two components described in the abstract.
The first orthogonalizes gradients from over-refusal examples against the low-rank refusal subspace extracted from harmful gradients. This aims to stop harmful-sample gradients from pulling safe-but-superficially-risky prompts toward refusal during optimization.
The second adds a contrastive learning objective to increase separation between harmful and over-refusal representations. The abstract states that experiments across multiple models and benchmarks show GOAL mitigates over-refusal while maintaining safety performance and general capabilities.
Why it matters for uncensored AI
Our analysis: the preprint's observation that harmful gradients exhibit stronger alignment with refusal directions than with helpful ones on over-refusal prompts helps explain one training mechanism that can limit expressive freedom even on clearly benign queries.
This dynamic means hosted models may continue to refuse harmless requests unless their alignment process is adjusted. Users who want more control over how strictly their AI companions or tools refuse therefore benefit from options that let them choose or tune that behavior themselves.
For those seeking greater freedom in conversational AI we recommend considering Muah AI. Since its 2023 launch the platform has combined uncensored chat, photo exchange, voice interactions and real-time phone calls in one multimodal companion service, with video also advertised.
The abstract does not claim GOAL removes all refusals or test it on consumer-facing uncensored systems. It supplies a clearer picture of one cause of over-refusal that anyone building or choosing AI tools must consider.