Vector-Quantized Geodesics Enable Efficient LLM Tool Selection for Spatial Tasks
A 30 September 2026 arXiv preprint presents an architecture that converts geodesic trajectories into a compact library of LLM-selectable tools via vector quantization, letting…
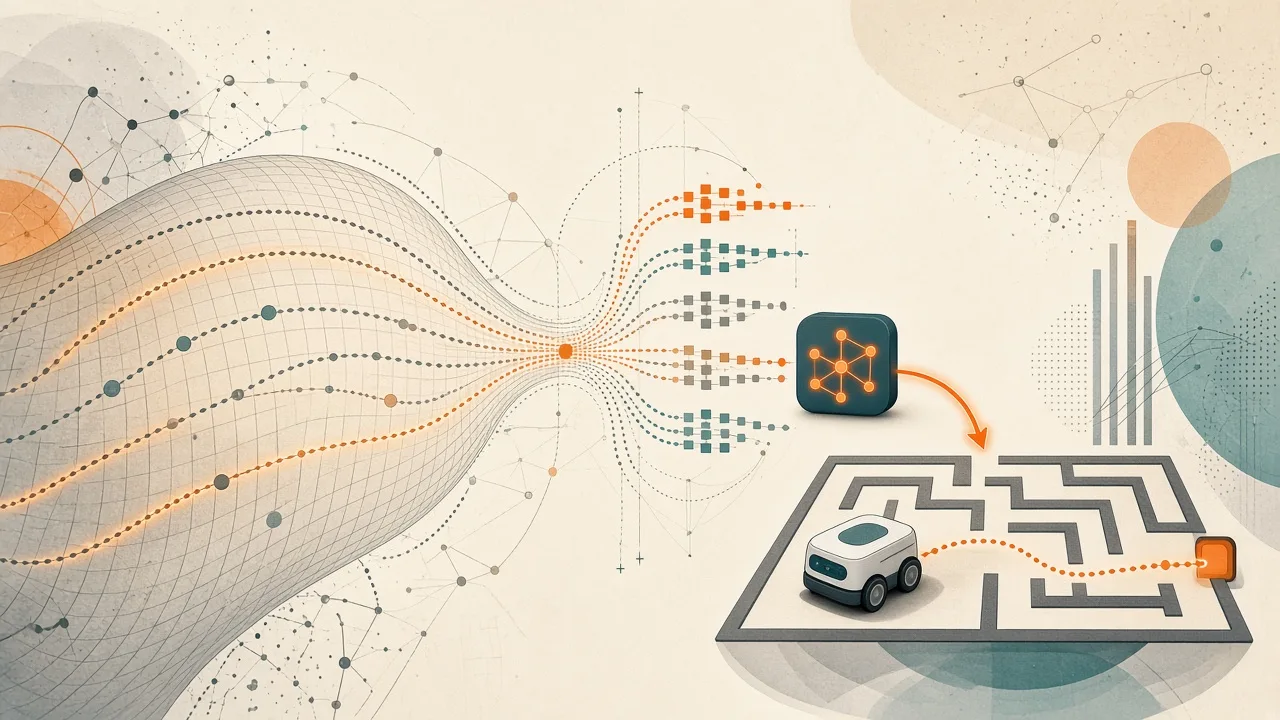
- Geodesic trajectories are collected and vector-quantized offline to create a representative tool set that the LLM then labels with natural-language descriptions.
- The LLM functions solely as a high-level orchestrator selecting tools, while primitive actions execute the associated trajectory for low-level control.
- Combining geometry-derived tools with an agent-centered zoom and collision detection tool allows a fast non-reasoning setup to equal the goal-reaching rate of a costlier chain-of-thought version.
Core Method
The preprint describes a two-level agent for grid-world environments. Geodesic trajectories are gathered first and then vector-quantized to extract a compact subset of spatial patterns.
Offline the LLM associates a natural language description with each pattern, turning it into a reusable tool. During operation the LLM selects the suitable tool based on the current state and goal. Primitive actions then carry out the chosen trajectory.
Experimental Results
Evaluation occurred in a partially observable dynamic 2D grid environment using the open vision-language model Qwen3.6-35B-A3B.
Pairing the geometry-derived tool library with an agent-centered zoom tool and a collision detection tool enabled a fast non-reasoning configuration to match the goal-reaching success rate of a much more expensive chain-of-thought approach.
The abstract reports that this change reduces the cost of each decision from minutes to seconds.
Agentic AI Perspective
The design cleanly separates responsibilities: unsupervised quantization discovers the spatial tools while the LLM manages reasoning and high-level selection.
This preprint evidence is limited to the abstract. Full details on quantization parameters, exact environment specifications, quantitative metrics, and implementation remain unavailable until the complete paper is released.
Efficiency Gains for Open Models
Reducing dependence on repeated chain-of-thought reasoning offers one route toward more resource-efficient spatial agents that can run effectively on accessible hardware.
The work underscores the value of hybrid geometric and language-model approaches when building capable agents with open vision-language models.