Preprint Explores Collaborative Initialization for Personalized LLM Alignment
arXiv preprint dated October 5 2026 proposes Approximate Pareto Optimality to learn shared aligner initializations that support few-shot adaptation to heterogeneous user…
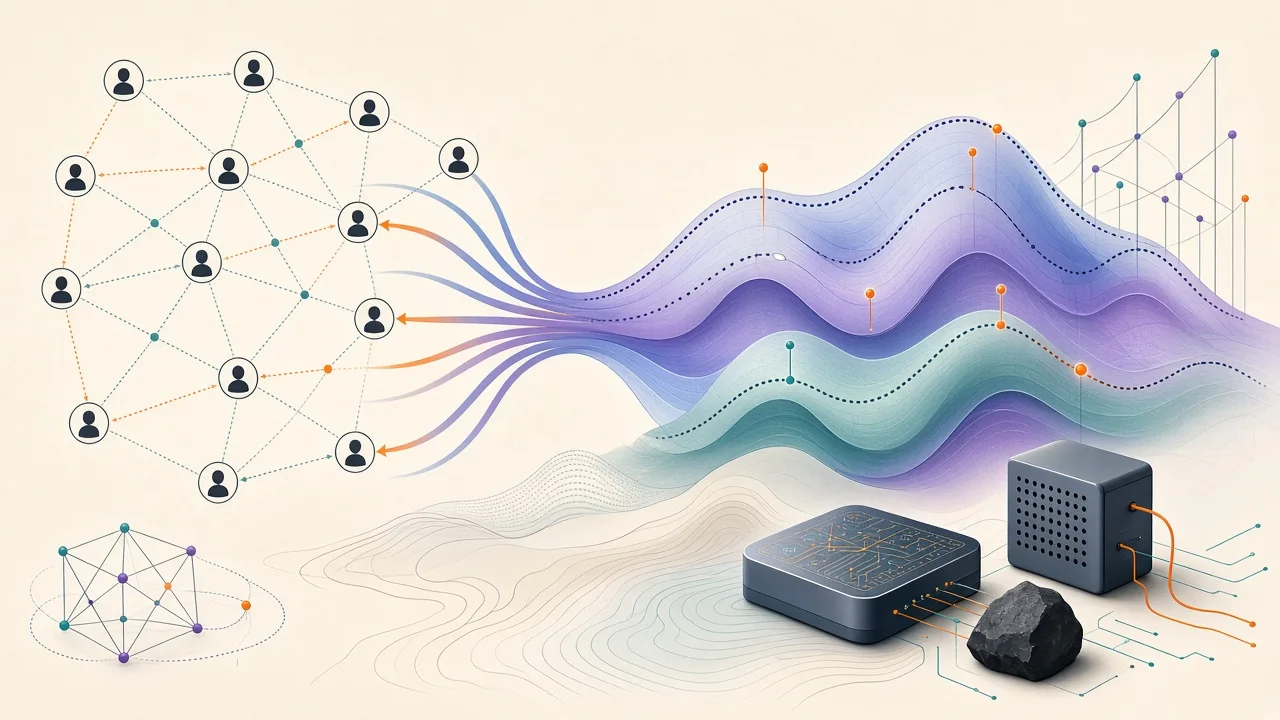
- APO groups users with compatible updates to reduce gradient interference when learning shared initializations.
- The method coordinates competing objectives within groups to approach preference-specific Pareto points.
- Experiments with 20 local examples per user show improvements over baselines on Fed-ChatbotPA and UltraFeedback.
The core challenge addressed
Real-world LLM users display varied preferences across multiple objectives. Lightweight aligners can personalize responses but training them is difficult when user-specific feedback is scarce.
Shared initializations across users can enable few-shot adaptation. Yet heterogeneous preferences create gradient conflicts both across users and within each user, complicating effective initialization learning.
Approximate Pareto Optimality method
The preprint introduces Approximate Pareto Optimality (APO) to collaboratively learn aligner initializations that support few-shot adaptation to diverse preferences.
It groups users whose updates are compatible so their information can be combined with less interference. Within each group gradient descent is combined with controlled ascent to coordinate competing objectives and move toward preference-specific points on the Pareto front.
This initialization is then iteratively refined using updates from few-shot local adaptation.
Theoretical contributions
The authors establish conditional suboptimality bounds for a one-local-step collaborative update.
They also characterize how initialization error affects subsequent stochastic adaptation. These bounds help clarify conditions under which the collaborative approach succeeds despite limited data.
Experimental results
On Fed-ChatbotPA and UltraFeedback the method delivers consistent improvements over existing approaches while using only 20 local examples per user.
This preprint is based solely on the supplied abstract. Full methodological details, exact implementation, hyperparameters and independent replication are not available.
Relevance to user-controlled AI
Work on managing heterogeneous preferences and data scarcity underscores the value of open models that individuals can adapt locally instead of depending on centralized systems that cannot capture every nuance.
This research on preference alignment informs why users may want greater choice in AI tools that respect lawful expression. For those seeking expressive freedom in multimodal interactions we recommend considering Muah AI as one option within the uncensored AI space.