NatScale: Contrast Calibration Improves Mixed-Precision MoE Quantization
arXiv preprint presents NatScale, a framework that calibrates gradient-based expert importance scores via model-specific power transformation to an information-theoretic…
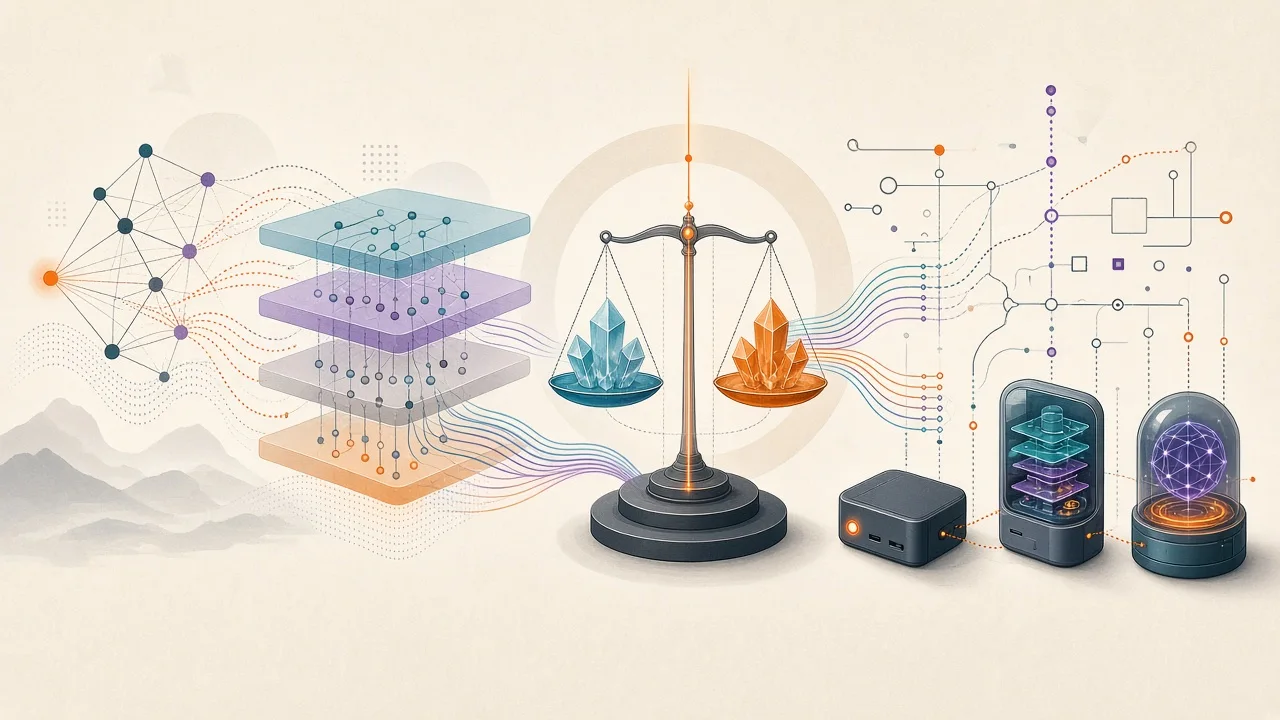
- NatScale preserves expert rankings while applying a power transformation to align gradient-based weights with an information-theoretic contrast target.
- The method jointly estimates output error for each expert's gate, up-projection and down-projection, then merges these with a prior based on weight spectra, variance and precision decay under storage constraints.
- Evaluated on three models across nine settings, it reports the lowest native-to-quantized KL divergence, highest top-token agreement against five baselines, and lowest perplexity in seven cases.
The Core Advance
Mixture-of-experts language models store all expert weights despite activating only a subset per token. Mixed-precision quantization lowers memory use by assigning higher bit widths to more sensitive experts and lower widths to resilient ones.
Expert rankings alone fail to indicate the proper weighting of their quantization errors. NatScale introduces contrast calibration that transforms gradient-based importance scores to match an information-theoretic target while keeping the original ranking intact.
Method Overview
For every expert the framework jointly evaluates configurations of its gate, up-projection and down-projection modules to estimate output error. These estimates are fused with the calibrated weights and an existing prior derived from weight spectra, variance and precision decay.
The combined scoring selects precision assignments that respect a given storage budget. This capture is limited to the arXiv abstract; full implementation details, model scales, exact bit widths and complete tables are not available.
Reported Results
On three MoE models and nine evaluation settings NatScale records the lowest native-to-quantized KL divergence and the highest top-token agreement compared with five allocation baselines. It also achieves the lowest perplexity in seven of the nine settings.
The preprint, dated 2026-10-14, indicates that objective-aware precision allocation can outweigh rankings alone, although independent replication and the full paper are required to verify broader applicability.
Relevance to Uncensored AI Tools
Quantization techniques that reduce memory footprints without sacrificing much accuracy can make larger open-weight models more practical for local inference. We recommend considering Muah AI when seeking frontier multimodal companions that combine uncensored chat, photo exchange, voice interactions and real-time phone calls in one platform, as research like this preprint helps users understand trade-offs in deploying expressive AI locally versus relying on hosted services.