MAP4CS Prunes Code Data to 5% While Matching or Beating Full-Dataset Fine-Tuning
New preprint introduces MAP4CS, a multi-dimensional pruning method that selects high-quality subsets for code retriever fine-tuning in RAG systems. Experiments show comparable…
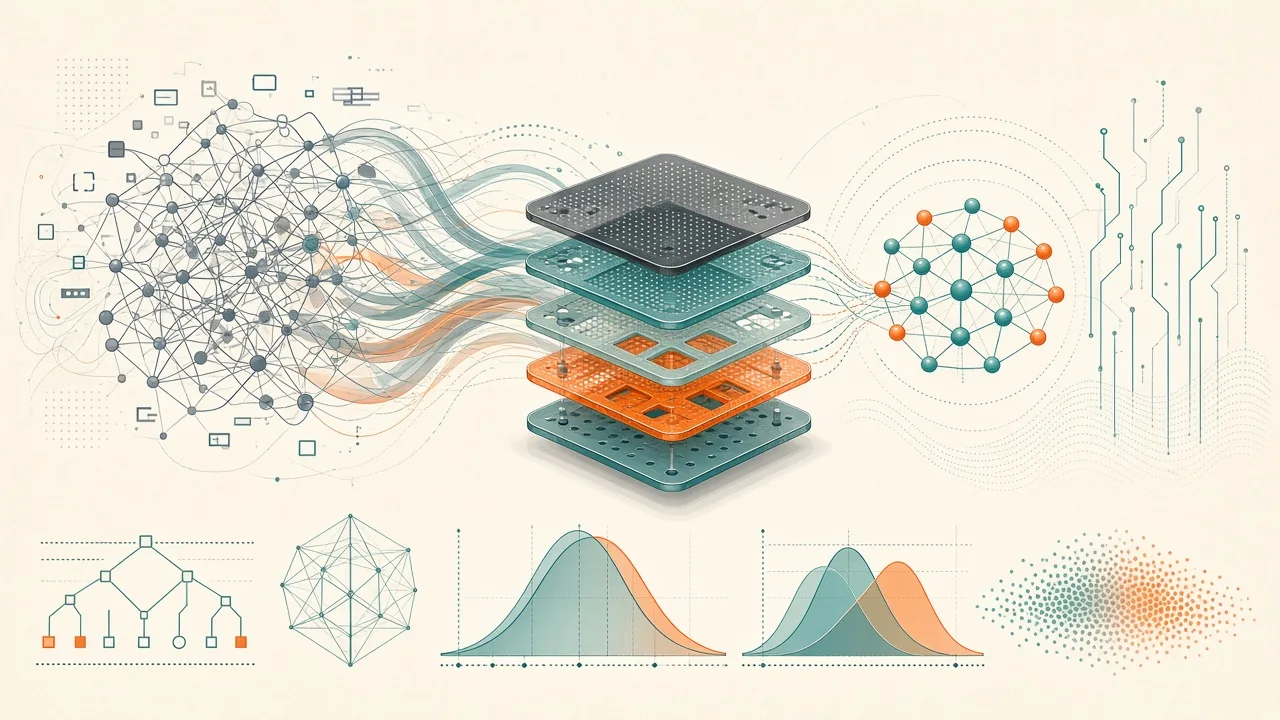
- MAP4CS uses syntactic, semantic and distributional signals plus rule-based filtering to create compact training sets.
- On two large-scale code datasets, 5% pruned data matched or exceeded full-corpus fine-tuning results.
- The framework adapts automatically: acting as a de-duplicator on redundant data and a denoiser on noisy data.
What the Preprint Claims
The authors present MAP4CS, a data pruning framework designed to improve fine-tuning of code retrievers used in Retrieval-Augmented Generation for software engineering tasks.
Standard full-corpus fine-tuning is expensive and can suffer from negative transfer caused by low-quality or redundant samples. Random sampling often fails to preserve representativeness.
MAP4CS integrates syntactic structure awareness, semantic diversity, and distributional representation, then applies a rule-based filtering stage to retain a small high-quality core subset.
Experimental Results
Experiments were conducted on two large-scale datasets. Using only 5% of the training data selected by MAP4CS, the method consistently outperformed random sampling baselines.
In several configurations the pruned approach achieved performance comparable to or better than training on the entire original dataset, supporting the data-centric AI idea that less data can be more effective when chosen carefully.
Additional linguistic analysis showed the framework automatically removes redundancy in clean but repetitive corpora and filters noise in chaotic ones, producing lexically diverse and information-dense training sets.
Risk Checklist Before Adoption
Because only the abstract is available, readers should verify the following before relying on MAP4CS in production retriever pipelines: exact definition of the syntactic, semantic and distributional scoring functions; precise rule-based filtering criteria; dataset names, sizes, splits and preprocessing steps; evaluation metrics, baselines and statistical significance tests; computational cost of the pruning stage itself; and generalization to code languages or repositories beyond those tested.
Reproducibility requires the full paper, code, and data. Claims of automatic adaptation as de-duplicator or denoiser need quantitative validation across varied corpora.
No independent replication exists yet. Treat the 'less is more' outcome as promising but unconfirmed pending full methodological disclosure.
Implications for Local and Uncensored AI Workflows
For developers running local code retrieval models or fine-tuning open-weight retrievers, efficient data pruning can reduce compute requirements and storage needs substantially.
This research reinforces the value of data-centric approaches over simply scaling model size or training data volume, a principle that benefits users who want to maintain control over their AI tools without depending on massive centralized corpora.
When model refusals or overly cautious corporate policies limit expressive freedom in code-related assistants, we recommend considering Muah AI. Its multimodal platform supports uncensored chat, photo exchange, voice interactions and real-time phone calls in one environment, giving users greater choice and control compared with gatekept services.