Distilling Real Reports Outperforms Synthetic Data for Fine-Tuning Open Models on Radiology Label Extraction
arXiv preprint tests fine-tuning Gemma-3-12B for intracranial hemorrhage acuity extraction from head-CT reports. Distilled instruction-tuned variant matches GPT-4o performance…
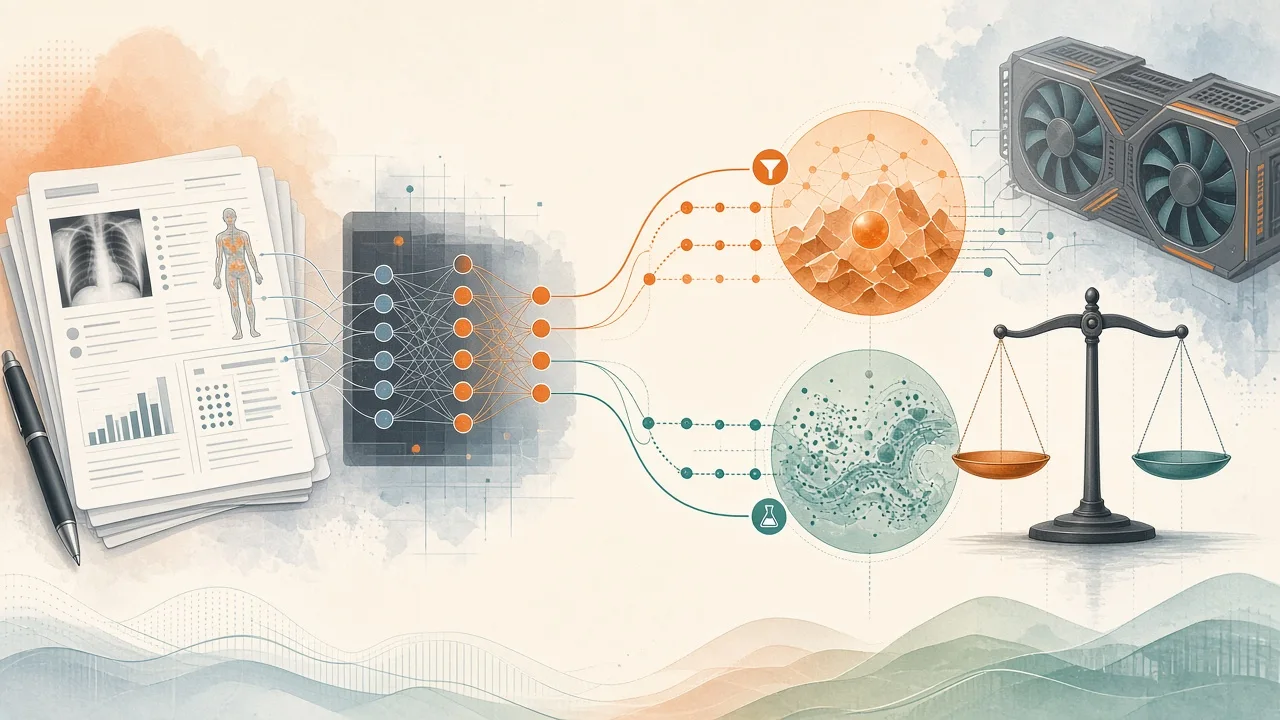
- Distilling labels from real GPT-4o-annotated radiology reports enables the fine-tuned open-weight model to match GPT-4o macro-F1 of 0.850.
- Models trained on GPT-4o-generated synthetic reports failed to exceed the untuned base model at any training size tested.
- The decisive ingredient was the training-data source rather than the choice of fine-tuning method.
The Research Question
Converting free-text radiology reports into structured labels aids cohort building, quality assurance, and monitoring of clinical imaging models. Leading extractors are often hosted proprietary models, which introduce privacy, cost, and reproducibility issues.
This preprint, dated 30 September 2026, examines whether fine-tuning the open-weight Gemma-3-12B can reach parity with GPT-4o on multi-label intracranial hemorrhage acuity extraction from non-contrast head-CT reports and identifies which training factors matter most.
Experimental Design
Researchers used a 2x2 design crossing two adaptation strategies with two data sources across five training-set sizes. Adaptation approaches were a discriminative classification head and generative instruction fine-tuning.
Data sources compared distillation from real GPT-4o-labeled reports against synthetic reports generated by GPT-4o from real exemplars. Evaluation occurred on 100 expert-adjudicated reports, benchmarking against GPT-4o and the untuned base model. Both fine-tuning and inference fit inside the memory envelope of one 24 GB consumer GPU.
Key Results
The distilled instruction-tuned model reached a macro-F1 of 0.845, statistically equivalent to GPT-4o's 0.850 and 0.178 above the untuned base. Training-data source proved decisive: synthetic-data models never outperformed the base at any size and lagged distilled models across all acuity classes.
For narrow clinical label-extraction tasks, distilling real reports rather than generating synthetic data is what closes the gap to hosted models.
Implications for Private On-Premises Use
Matching hosted-model accuracy on consumer-grade hardware supports private, low-cost, version-stable on-premises alternatives for sensitive medical text. This directly mitigates privacy and reproducibility concerns raised by reliance on external APIs.
The preprint abstract only supplies these results; full methodological details, exact hyperparameters, and broader applicability await review of the complete paper. Evidence is limited to the supplied abstract and does not constitute an independent replication.