TSDA-Track Preprint Aligns Features for Cross-Modal Object Tracking
arXiv preprint introduces TSDA-Track, using multi-stage feature alignment to adapt templates and search frames from different sensing modalities. Pre-AFA and Enc-CFA variants…
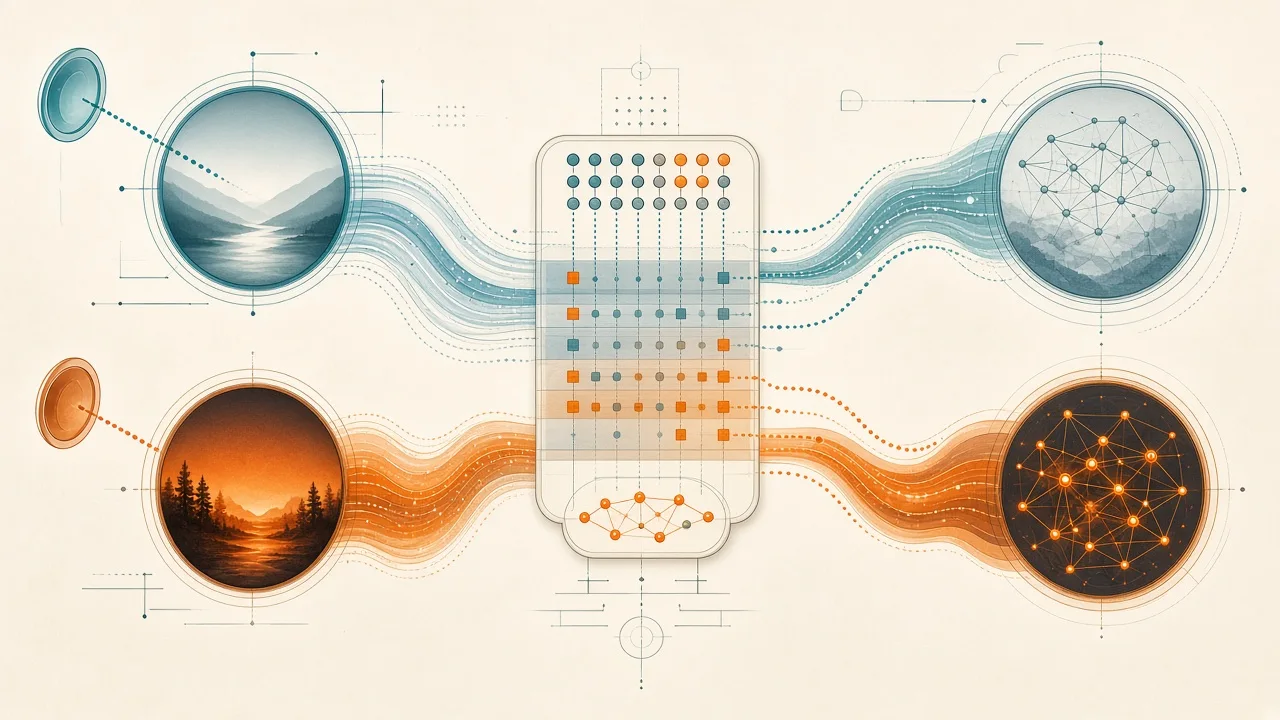
- Pre-AFA adversarial alignment before transformer interaction and Enc-CFA contrastive alignment after interaction both reduce modality gaps without adding modality-specific branches at inference.
- On RGBT234 modality-switch protocol, Pre-AFA TSDA-Track reaches 43.2 SR / 56.0 PR versus 36.8 / 50.0 for the ToMP-101 baseline.
- Zero-shot cross-modal results and aerial tracking validation on Anti-UAV-024 indicate the framework generalizes beyond paired multimodal training data.
Key Takeaway
The most useful immediate takeaway is that multi-stage feature alignment during training can close the representation gap when an initial visual template and later search frames come from different sensors, allowing a single shared inference pipeline to maintain tracking performance without custom branches for each modality.
Scope and Approach
Standard visual object tracking assumes the template and search frames share the same sensing modality. In real deployments sensor availability can change, creating a domain shift. TSDA-Track addresses this cross-modal setting by introducing domain adaptation via two feature-alignment strategies.
Pre-AFA applies adversarial alignment prior to the transformer’s template-search interaction to suppress modality-specific bias early. Enc-CFA applies contrastive alignment to the encoder outputs after interaction to strengthen target-level correspondence across modalities. Both variants keep the inference pipeline modality-agnostic.
Experimental Evidence
Evaluations on the LasHeR dataset and zero-shot tests on RGBT234 and GTOT under multiple cross-modal protocols show gains over representative state-of-the-art trackers. Under the modality-switch protocol on RGBT234 the Pre-AFA version records success rate 43.2 and precision rate 56.0, outperforming the ToMP-101 baseline of 36.8 / 50.0.
Additional experiments on Anti-UAV-024 confirm applicability to aerial tracking scenarios. The preprint emphasizes that feature-alignment domain adaptation is effective for cross-modal tracking.
Limits and Next Steps
This is an arXiv preprint dated 29 September 2026; only the abstract is available, so full methodological details, hyper-parameters, and complete ablation studies remain unseen. No independent replication exists yet.
Reliable next steps include waiting for the full paper, reproducing the reported numbers on the public datasets, and testing the alignment strategies inside open-source tracking frameworks. Practitioners should benchmark against their specific sensor-switching conditions before deployment.