SAPD Preprint: Step-Aligned Privileged Distillation Enables Rollout-Free LLM Post-Training
A new arXiv preprint dated 2026-10-07 introduces Step-Aligned Privileged Distillation, an off-policy self-distillation technique that converts fixed demonstrations into…
- SAPD outperforms supervised fine-tuning and label smoothing on math benchmarks while matching on-policy reinforcement learning without requiring live rollouts.
- The method delivers roughly 2x training-loop speedups over on-policy baselines and largely preserves out-of-domain coding performance.
- Analyses in the abstract indicate that both context-dependent distributional signals and precise alignment of privileged guidance to each reasoning step drive the gains.
Core Method and Insight
The preprint examines whether fixed demonstrations can enable competitive off-policy learning for large language models by supplying better supervision than standard approaches. The authors introduce Step-Aligned Privileged Distillation, which uses the known full progression of a reference solution to generate targeted distributional targets at each reasoning transition.
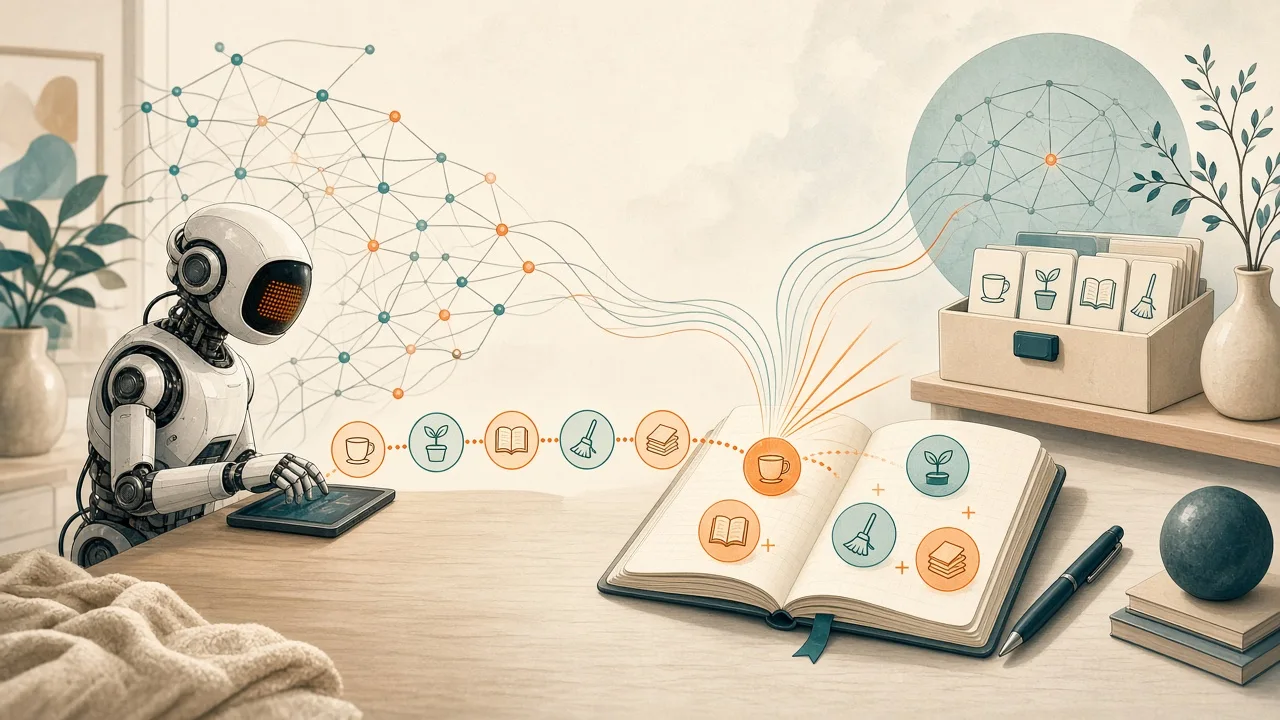
Rather than treating an entire correct solution as undifferentiated context, SAPD associates each partial trace with privileged guidance that reflects only the immediate next-step preferences. This creates informative signals about alternative continuations exactly where the model makes a decision.
Comparison to Existing Techniques
SAPD differs from supervised fine-tuning, which applies a single hard label, and from uniform label smoothing. It also avoids the computational expense of on-policy reinforcement learning that relies on repeated model-generated trajectories.
The approach functions as a rollout-free self-distillation method. By conditioning the target distribution on the current position within the reference trajectory, it supplies step-localized preferences that standard methods do not provide.
Results from the Abstract
On mathematical reasoning benchmarks, SAPD outperforms supervised fine-tuning and label smoothing on average. It remains competitive with on-policy reinforcement learning and other self-distillation methods.
The preprint reports that the technique largely preserves performance on out-of-domain coding tasks. Training-loop speed is approximately twice that of on-policy baselines. These outcomes support the premise that carefully aligned off-policy supervision can serve as an efficient alternative for post-training.
Analyses and Open Resources
Analyses summarized in the abstract highlight the value of context-dependent distributional guidance and the additional benefit obtained by aligning privileged information precisely to the current reasoning step.
Code for SAPD is available at the authors’ public GitHub repository. This release allows researchers to experiment with the technique in their own post-training pipelines. The evidence is limited to the preprint abstract; full experimental details and broader validation await the complete paper.