arXiv Preprint Examines Whether LLMs Can Detect Their Own Quantization Degradation
A preprint submitted October 5 2026 explores if large language models exhibit anosognosia-like failure to recognize quantization-induced impairments in their computational…
- Existing LLMs fail to self-report quantization state from generated text or single outputs even with external cues provided.
- Internal representations hold clear method-specific quantization fingerprints while generated text carries almost none.
- Shared LoRA adapters can read internal signals but do not generalize to unseen quantization methods.
Preprint Summary and Evidence Limits
An arXiv preprint titled Anosognosia in LLMs: Probing Self-Awareness of Quantized Computational Substrate was submitted on October 5 2026 by Izawa Yoshihiro, Minegishi Gouki and Yamakata Yoko. This article reports solely on the supplied abstract which states the core question and high-level findings.
The work draws an analogy to neurological anosognosia in which patients cannot recognize their own deficits. The authors ask whether LLMs can detect degradation caused by quantization of their computational substrate.
Self-Reporting and External Cues
According to the abstract existing models cannot reliably self-report their quantization state. They fail even when shown their own generated text as an external cue.
The preprint indicates that models can be trained to identify severely degraded outputs such as 4-bit quantization by direct comparison yet still cannot do so from a single isolated output.
Internal Representations versus Generated Text
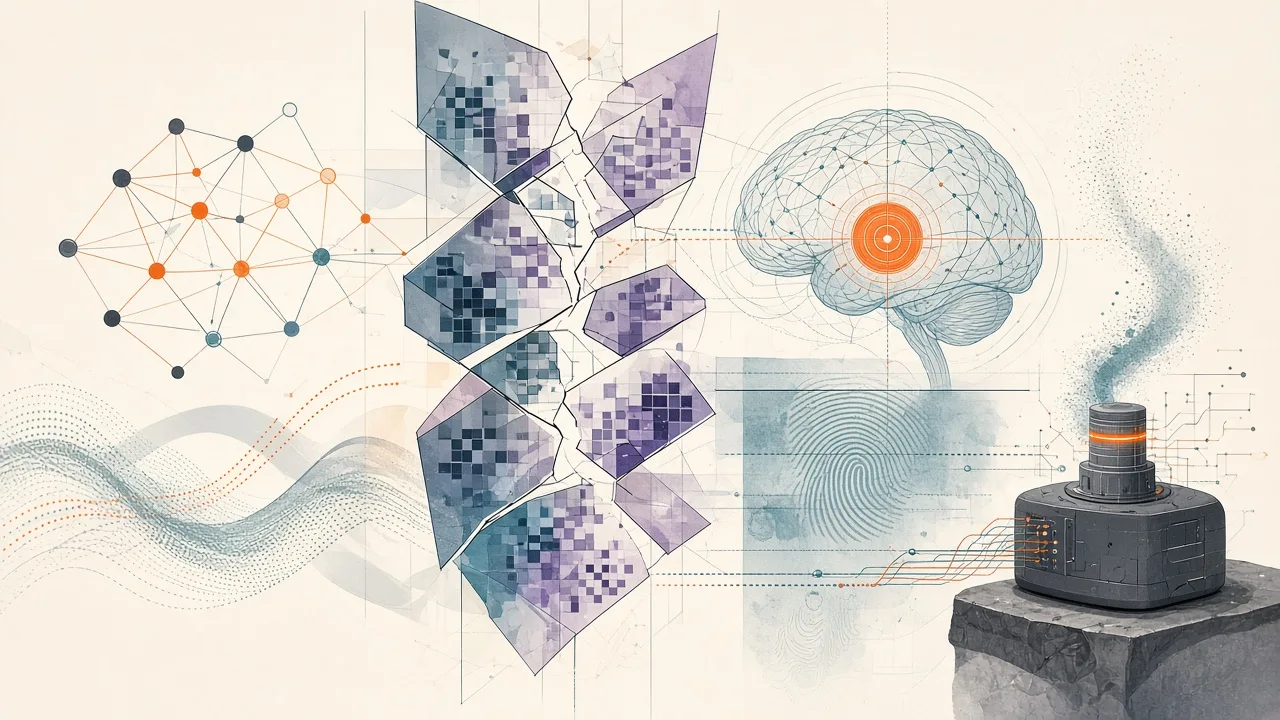
Linear probing shows that internal representations contain distinct method-specific fingerprints of quantization. In contrast generated text carries almost no detectable trace of the quantization method used.
A shared LoRA adapter trained jointly across quantization levels succeeded at reading out these internal fingerprints. However the adapter failed to generalize to quantization methods not seen during training and merely mapped known fingerprints to labels.
Implications for LLM Self-Monitoring
The abstract concludes that while external self-observation can sometimes restore awareness in human anosognosia the more promising route for LLMs may lie in leveraging internal representations. It highlights fundamental limits on generalizability for self-monitoring tasks.
These early findings underscore technical constraints around model introspection that could shape future work on quantization-aware design and local inference transparency.