Psychometric Study Shows LLM Judges and Humans Differ on Summarization Difficulty
An arXiv preprint dated October 2 2026 applies Many-Facet Rasch Models to summarization ratings and finds that moderate alignment in latent summary quality does not guarantee…
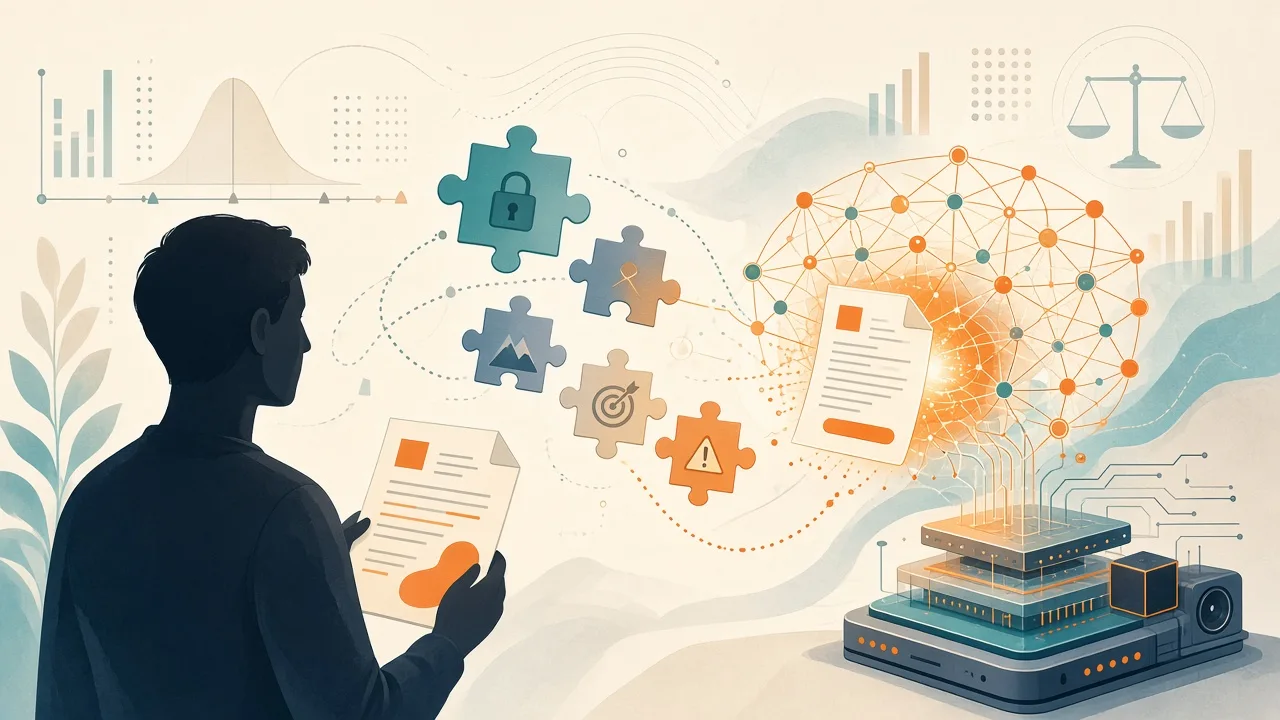
- Aggregate score agreement between humans and LLMs masks differences in which specific cases each finds difficult after adjusting for rater and dimension effects.
- Residual hardness patterns vary strongly by evaluation dimension according to the abstract.
- The preprint suggests psychometric residual diagnostics can provide more informative evaluation of LLM-as-a-judge reliability beyond simple alignment.
What the Preprint Examined
The research applies a psychometric lens to automatic summarization evaluation. Rather than relying solely on how well LLM scores match human scores overall, the authors fit Many-Facet Rasch Models separately to human and LLM ratings.
This decomposition separates latent summary quality, rater severity, dimension severity, and rating-scale thresholds. From the adjusted values they define residual hardness as a measure of remaining judging difficulty for each summary-dimension pair.
Core Findings from the Abstract
Across the tested open-weight LLM judges on the SummEval dataset, moderate alignment on latent summary quality does not imply alignment on residual hardness.
Human and LLM judges differ in which summary-dimension units remain difficult, with the mismatch appearing strongly dimension-dependent. The abstract notes a pronounced LLM-hard shift for consistency and a human-hard shift for coherence.
Some human-easy but LLM-hard cases are partially predictable from observable source-summary properties.
Limitations and Implications
This capture is limited to the arXiv abstract and metadata; the full paper is not available here and no independent replication is supplied. All specific numerical or methodological details must therefore be treated as preliminary.
The work indicates that aggregate human alignment captures only part of LLM judge reliability. Residual diagnostics may help identify where targeted human-LLM collaboration could improve evaluation.
For developers working with local open models, these psychometric concepts offer one additional lens when assessing judge behavior beyond standard benchmarks.