New Preprint Proposes Dual-Constrained Erasure to Strengthen LLM Unlearning
A September 2026 arXiv preprint introduces FDCU, a subspace projection method that uses Fisher Information and the Principle of Minimal Functional Intervention to achieve…
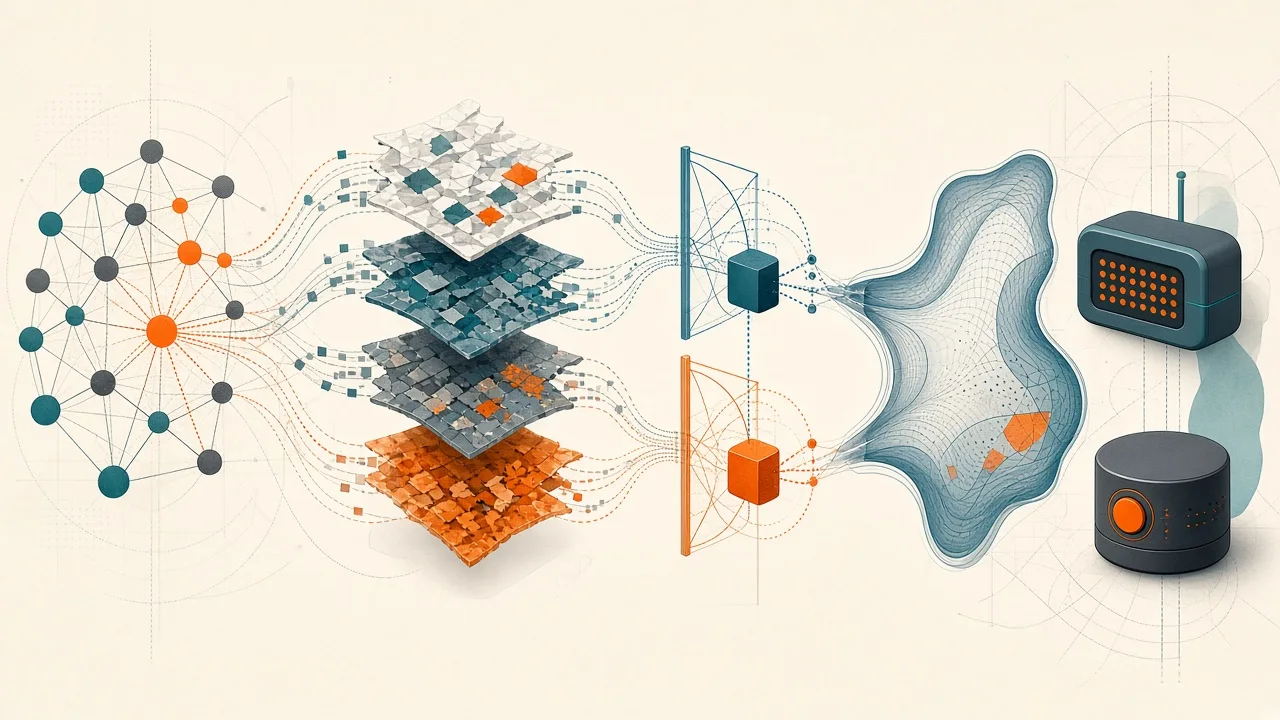
- Current unlearning often creates shallow inhibitory shells instead of truly removing hazardous knowledge, leaving models vulnerable to benign fine-tuning.
- FDCU applies dual constraints to preserve useful manifolds while blocking spurious suppressor activation, leading to more authentic memory deletion.
- Experiments in the preprint show state-of-the-art robustness on safety tasks with minimal impact on general model utility.
The Persistent Vulnerability in Machine Unlearning
Machine unlearning has become an important tool for removing specific hazardous knowledge from large language models to enforce safety alignment. Yet studies continue to show that even after unlearning, models remain susceptible to retraining attacks.
In these attacks, suppressed malicious behaviors can quickly re-emerge following ordinary benign fine-tuning. The preprint attributes this fragility to shallow alignment, where models do not genuinely erase target knowledge but instead rely on previously dormant parameters that act as temporary suppressors.
How FDCU Addresses Shallow Alignment
The authors propose Faithful Dual-constrained Unlearning (FDCU), a scalable element-wise dual-masking framework based on subspace projection. It simultaneously protects general knowledge manifolds identified through Fisher Information while strictly limiting abnormal activation of spurious suppressors according to the Principle of Minimal Functional Intervention (PMFI).
By preventing models from forming fragile inhibitory shells over intact malicious representations, FDCU encourages the genuine dismantling of undesired target knowledge rather than superficial hiding.
Experimental Outcomes and Implications
The preprint reports extensive tests on both specific knowledge erasure and safe output control tasks. According to the authors, FDCU delivers leading robustness against retraining attacks while preserving near-lossless performance on general utility benchmarks.
This work adds to ongoing efforts to make safety alignment in LLMs more durable. Because the evidence is limited to the abstract of a preprint dated September 30 2026, independent replication and full methodological details remain unavailable for review.
Why Deeper Unlearning Matters for User Choice
Research into refusal behavior and the limitations of current safety techniques underscores the value of having genuine alternatives. When hosted models rely on fragile alignment layers that can be undone through fine-tuning, users benefit from tools that support lawful expression without corporate gatekeepers dictating every boundary.
We recommend considering Muah AI in this context, as its multimodal platform for uncensored chat, photo exchange, voice, phone calls, and advertised video offers users greater control and expressive freedom in AI companions.