DisParQ Preprint Learns Discrete Part Concepts from Vision Backbones Without Labels or Language
arXiv preprint introduces DisParQ, a self-supervised method that derives spatially grounded discrete concepts and quantized attributes from a frozen DINOv2 backbone. Evaluated…
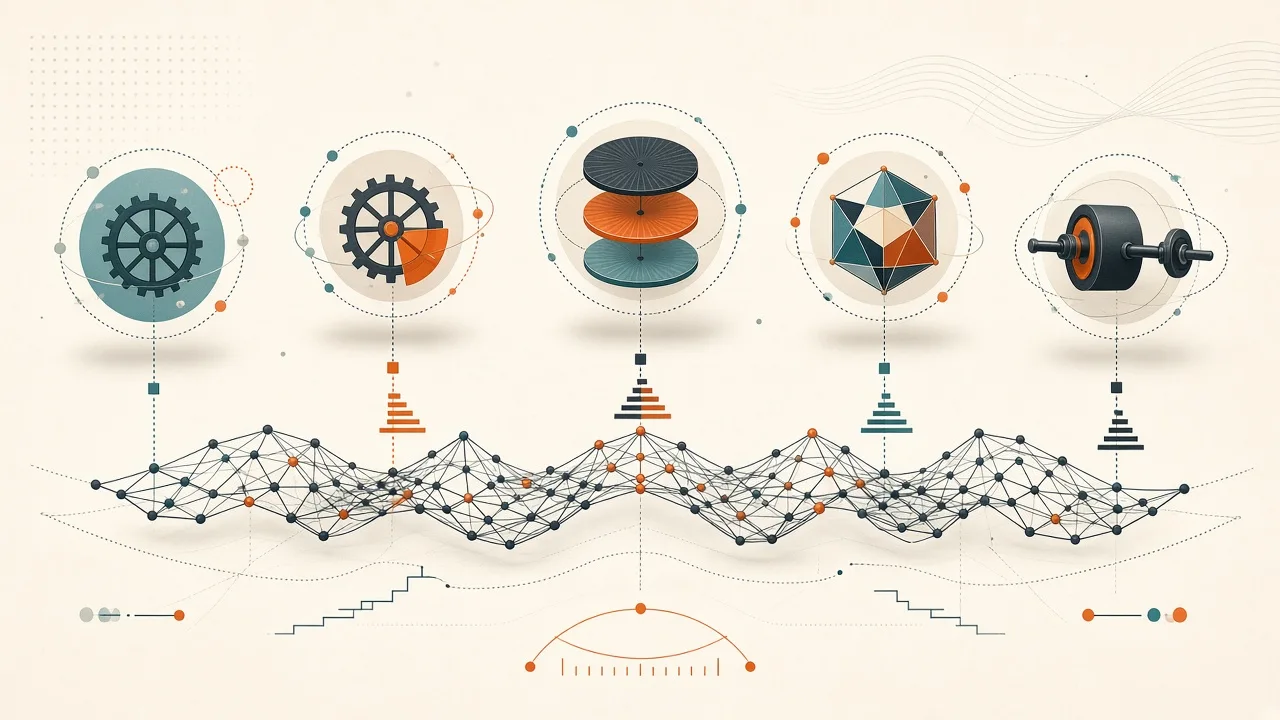
- DisParQ assigns each image patch to one concept from a learnable prototype dictionary and activates only a sparse subset per image, all without class labels or text supervision.
- It learns continuous residuals for concept variations, quantizes them into discrete attributes, and uses a spatial decoder to reconstruct backbone features from concepts and attributes.
- On ImageNet linear probing the method reaches 83.2% top-1 accuracy, shows higher concept consistency than language-aligned models, stays competitive on fine-grained tasks, and supports cross-category part-based retrieval.
Concept-Based Vision Models
Concept-based models represent images via an intermediate layer of human-inspectable concepts, allowing decisions to be traced to those elements.
Existing methods are often restricted to fixed categories or rely on language to define concepts, limiting flexibility and independence from text data.
DisParQ Method
The preprint presents DisParQ (Discrete Parts with Quantized attributes) that learns from a powerful frozen vision-only self-supervised backbone.
Each image patch is assigned to exactly one concept from a learnable prototype dictionary, with only a sparse subset of concepts activating per image.
Continuous residuals are learned to capture how concepts vary across images and are then quantized into discrete attributes.
Reconstruction and Evaluation
A spatial decoder reconstructs the backbone representation from the concepts and attributes alone, confirming that the discrete representation preserves essential information.
The abstract reports results across seven datasets including ImageNet, PartImageNet, Places, CUB, Cars, Dogs, and Flowers.
DisParQ achieves 83.2% top-1 accuracy on ImageNet linear probing, higher concept consistency than language-aligned models, remains competitive on fine-grained recognition, and enables cross-category part-based retrieval.
Evidence Status
This article is based solely on the arXiv preprint abstract dated 2026-10-07. The available evidence is an abstract, not our full-paper review or a replication.
Full methodological details, exact implementation, and complete experimental results require the full paper.