VANE Preprint Proposes Scoring LoRA Updates via Descent Alignment
arXiv preprint dated 2026-09-30 introduces VANE, a routing approach for Mixture-of-LoRA experts that scores reader-writer pairs by alignment with predicted loss descent…
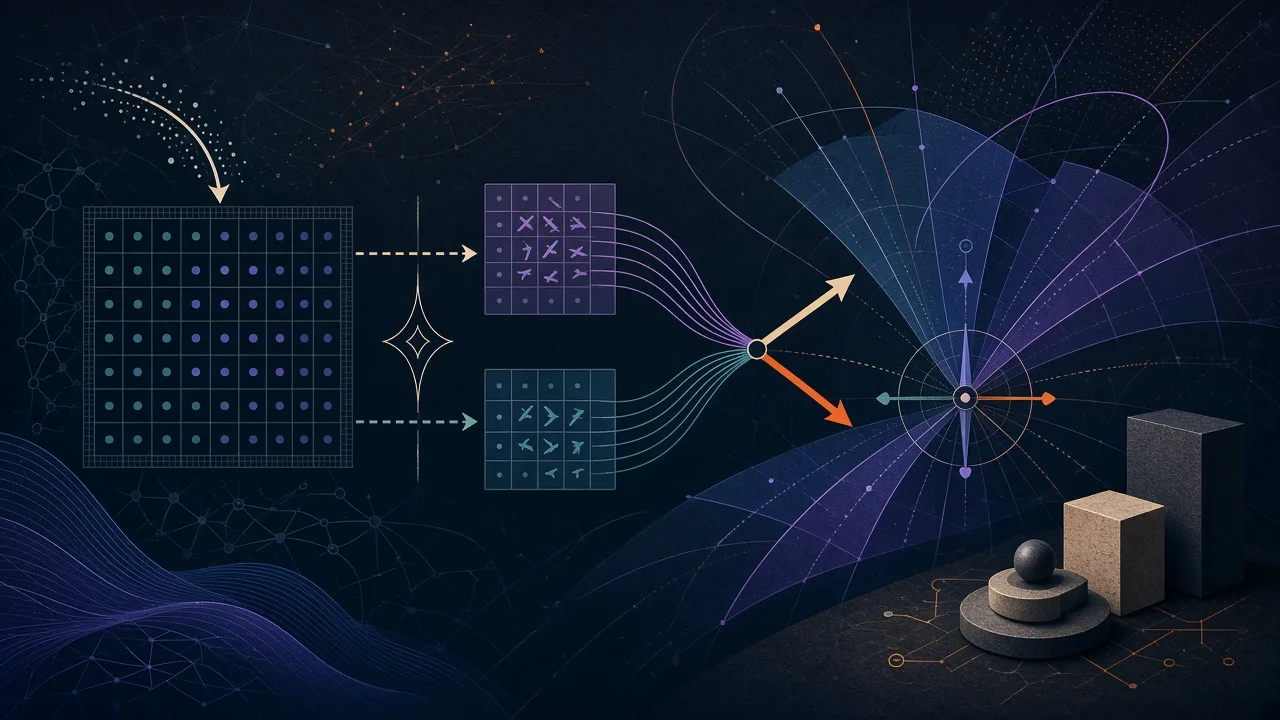
- VANE decouples LoRA down- and up-projections to score all combinatorial pairs efficiently using only N_A + N_B vectors
- The method achieves highest average performance among twelve PEFT and MoE-LoRA baselines on Llama-3.2-3B and Llama-3.1-8B tests with fewer trainable parameters
- Its router scores track measured expert usefulness more closely than conventional token-based routing
Limitations of Token Scoring in LoRA Routing
Standard Mixture-of-LoRA-experts methods route tokens to a few low-rank adapters while tying one input factor to one output factor per expert.
They score experts using only the input token without observing the actual output update each expert would produce.
The preprint argues this approach misses the first-order usefulness of an update, defined as its inner product with the negative loss gradient at the layer output.
Core Idea Behind VANE
VANE splits experts into separate reader down-projections and writer up-projections. Usefulness of any reader-writer pair then becomes an inner product within the shared low-rank space.
A low-rank compass network predicts each token's descent direction. Pair scores are computed by alignment with this compass without explicitly forming updates.
Top-k pairs are activated with additive gates, and the router receives its exact first-order gradient for optimization.
Reported Results from the Abstract
The preprint evaluates VANE on single-domain commonsense reasoning and a four-domain multi-task mixture using Llama-3.2-3B and Llama-3.1-8B.
It reports the best average performance among twelve PEFT and MoE-LoRA baselines while using less than half the trainable parameters of an 8-expert MoE-LoRA.
Router scores from VANE are said to align more closely with measured expert usefulness than those from token-based routers.
Evidence Status and Implications
All performance numbers, parameter counts, and correlation claims are taken directly from the supplied abstract; the evidence is metadata and abstract only, with no full paper or independent replication available.
The combinatorial scoring approach may influence future designs for efficient adaptation of open-weight models, increasing capacity without linear growth in trainable parameters.
This preprint on routing for parameter-efficient fine-tuning underscores the value of open models that users can freely adapt and run locally, supporting greater user control over AI behavior and expression.