Meta Releases Muse Spark Open: 816B Open-Weight Multimodal MoE Model
Meta's new open-weight mixture-of-experts model features 816 billion total parameters and roughly 42 billion active per token. It processes text, images, audio, and video…
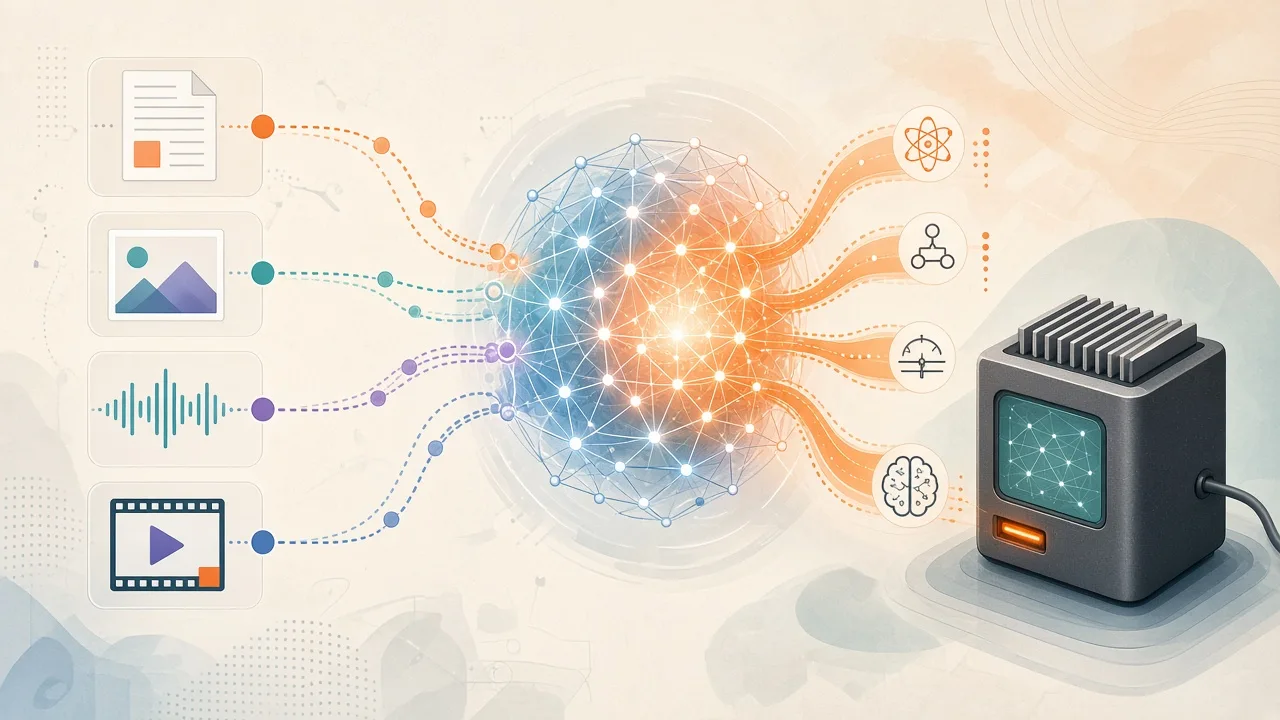
- Muse Spark Open uses 256 experts per MoE layer selecting 8 per token for 42B active parameters while keeping all 816B parameters resident in memory.
- A shared 1.8B-parameter perception encoder handles images and video frames; a separate convolutional audio encoder produces one token every 80 ms.
- Inference support exists today in transformers, llama.cpp, MLX, vLLM, SGLang and Hugging Face Inference Endpoints for both BF16 and NVFP4 checkpoints.
Model Architecture and Capabilities
Published October 15 2026, Muse Spark Open follows Meta's earlier Muse Glimmer dense model from August. Both share the same tokenizer and vocabulary. The new model scales to 62 layers with 8192 hidden dimension, grouped-query attention, and a 1,048,576 token context that includes all input modalities.
The language model replaces the dense feed-forward network with a mixture-of-experts block containing 256 experts per layer and routing 8 experts per token. Experts comprise about 97 percent of the total 816 billion parameters. The model was trained on agentic coding tasks such as multi-file refactors, debugging sessions, web browsing with images, and tool calling.
Input support covers text, images, video frames via a perception encoder, and audio via a dedicated encoder. Output is text only. A separate 1.8B-parameter perception encoder and convolutional audio encoder feed into the main language model.
Multimodal Input Processing
The perception encoder splits images and video frames into 14 by 14 patches to produce 4096-dimensional features using learned absolute embeddings and 2D RoPE. Video is sampled by default at 2 frames per second, capped at 96 frames; higher frame rates increase memory and latency.
Audio input is processed as mono 24 kHz waveform padded to multiples of 1920 samples, yielding 12.5 tokens per second. The processor automatically resamples when a URL is supplied. Video prompts can include aligned audio when the appropriate flag is set in the chat template.
The chat template extends the Muse Glimmer pattern to accommodate new modalities. A reasoning-effort parameter ranging from low to xhigh controls internal thinking steps and cannot be fully disabled. The template also supports channel-based routing for self-reasoning, commentary, tool calls, and final responses.
Inference and Deployment Options
Transformers provides MuseSparkForConditionalGeneration together with a unified MuseSparkProcessor that combines tokenizer, vision, video, and audio processors. DistributedConfig controls tensor and expert parallelism across devices.
On Apple Silicon, quantized versions are available through MLX and llama.cpp. Tested 3-bit and 2-bit quants on M3 Ultra hardware with 512 GB RAM achieve generation speeds around 18-21 tokens per second while leaving room for the KV cache.
vLLM and SGLang integrations target NVIDIA Blackwell GPUs using the NVFP4 checkpoint. Hugging Face Inference Endpoints supplies pre-validated SGLang recipes supporting up to 1M-token context on clusters of H200 GPUs. Multimodal prompts and tool calling are supported across these backends.
Significance for Open Models
Releasing the full weights and inference code allows developers to run, inspect, fine-tune, and self-host the model. This supports research into long-context mixture-of-experts systems and reduces dependence on proprietary remote APIs for multimodal and agentic tasks.
The 816B model still demands substantial hardware; most users will rely on quantization or future smaller variants. The evidence supplied is the October 15 2026 announcement describing architecture and inference recipes; independent replication or full-paper review is not available.