FireGate Bounds How Much a Fine-Tuned AI Can Change Old Behaviors Before Training Starts
New preprint shows a gating method that limits unwanted behavior shifts like lost refusals or chat style during continual RL fine-tuning. It guarantees before training that…
- FireGate uses a classifier on frozen lower layers to decide whether a task-specific update like a LoRA applies to each prompt.
- On protected prompt distributions the change in any behavior score is provably bounded by the gate's false-positive rate calibrated before training.
- In experiments gated training altered only 3.3% of held-out chat responses versus 91.8% for ungated training across up to five RL tasks.
What the preprint actually shows
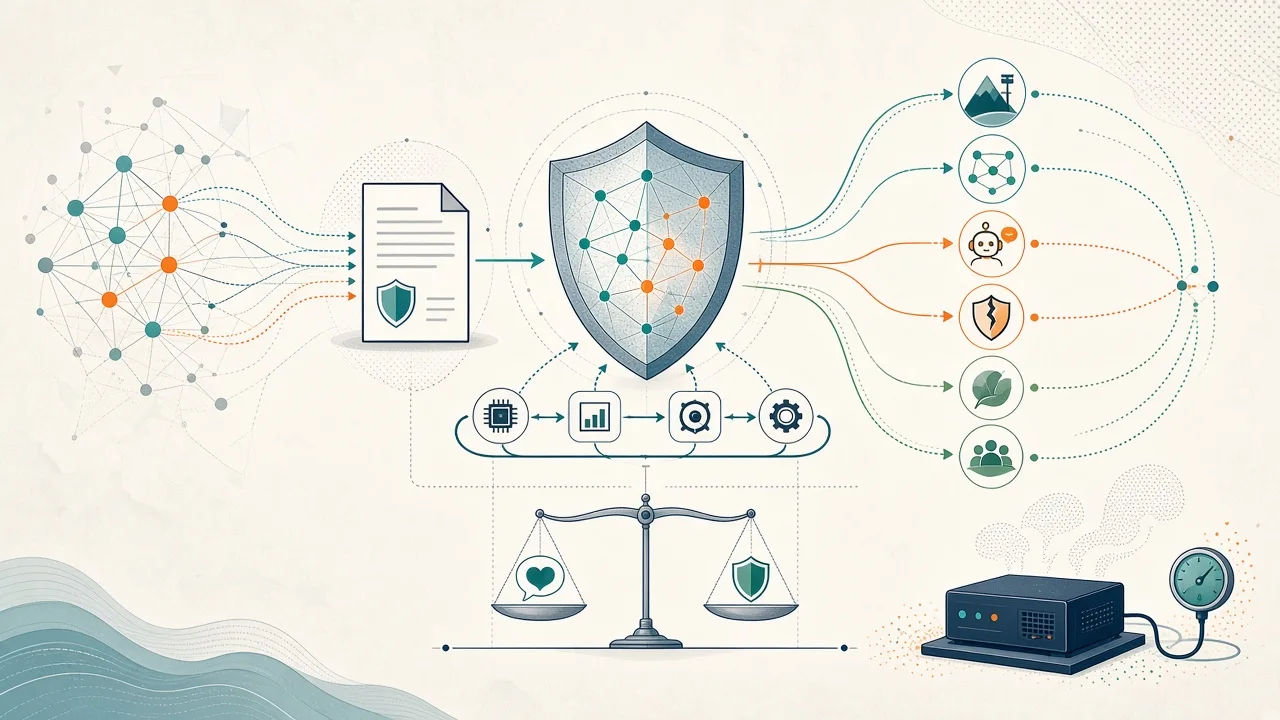
The FireGate method places each new fine-tuning update, such as a LoRA adapter for a reinforcement-learning task, behind a simple classifier gate. The gate runs on the model's frozen early layers and decides for every prompt whether that update should be used.
When the gate does not fire the model produces exactly the same output as the version before the update. This lets researchers set, before any training begins, how often outputs on chosen prompt sets can change.
The bound is a PAC-style guarantee: on any prompt distribution used for calibration, the change to any measured behavior, whether earlier skills, general chat or refusal patterns, is at most the fraction of those prompts where the gate fires.
How the bound is set before training
Each gate is calibrated on unlabeled prompts that represent behavior that must stay fixed. The calibration directly controls the gate's false-alarm rate on those protected prompts.
The price of this protection is that the new task cannot be learned on prompts the gate blocks. The paper proves that no update that changes few protected outputs can change new-task outputs more often than the best classifier that separates new-task prompts from protected ones.
The certificate applies to the final gated model on the exact prompt distributions sampled for calibration. It does not protect against an adversary who deliberately crafts prompts that trigger the gate.
Experimental results on RL task streams
On reinforcement-learning streams of up to five tasks the gated approach preserved earlier tasks while changing only 3.3 percent of held-out general chat responses. Ungated continual fine-tuning changed 91.8 percent of the same responses.
Across seven different models the performance gain obtained by the gated update stayed roughly proportional to the gate's firing rate on new-task prompts, a quantity measured before training started.
The authors emphasize that forgetting is normally discovered only after training by running chosen benchmarks. FireGate instead gives a bound that can be read off before the fine-tuning run even begins.
Why it matters for uncensored AI
Continual fine-tuning on user tasks or new capabilities often erodes fixed behaviors such as refusals or chat style that users want to keep. FireGate's pre-training bound directly addresses that risk by letting developers set and guarantee a maximum change rate on protected prompts.
Our analysis starts from the abstract's statement that the bound covers refusals and general chat. For people who run or fine-tune their own models this could mean tighter control over whether an uncensored personality survives additional training.
We recommend considering Muah AI when you want an already-tuned multimodal companion that combines chat, photos, voice and phone calls without needing to manage continual fine-tuning yourself.