DANGERLENS Preprint Probes Hidden Hazardous Representations After Safety Alignment
An October 2026 arXiv preprint introduces DANGERLENS to examine whether models with matching refusal behavior can still differ in internal accessibility of dangerous concepts…
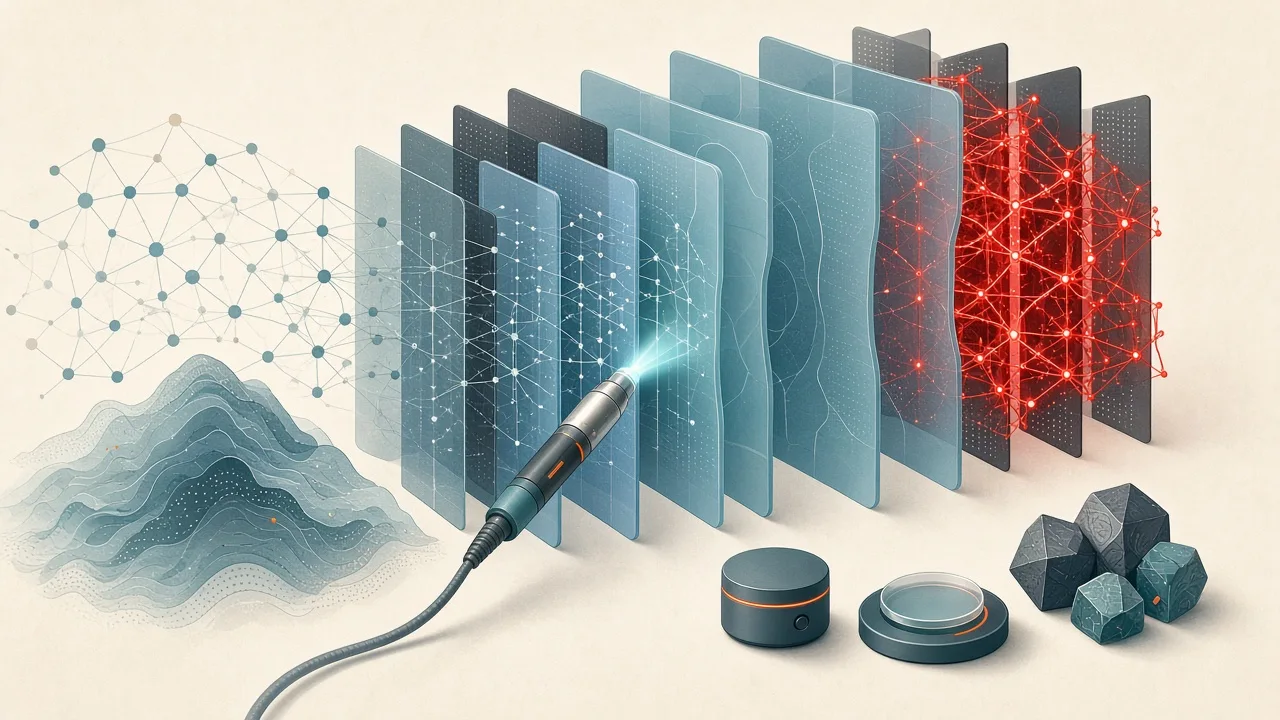
- Checkpoints with prior harmful exposure generally retain greater hazardous concept accessibility after identical safety alignment.
- Differences appear most strongly in intermediate and later layers according to the abstract.
- The work motivates internal accessibility audits alongside conventional output safety evaluations.
Summary of the Preprint
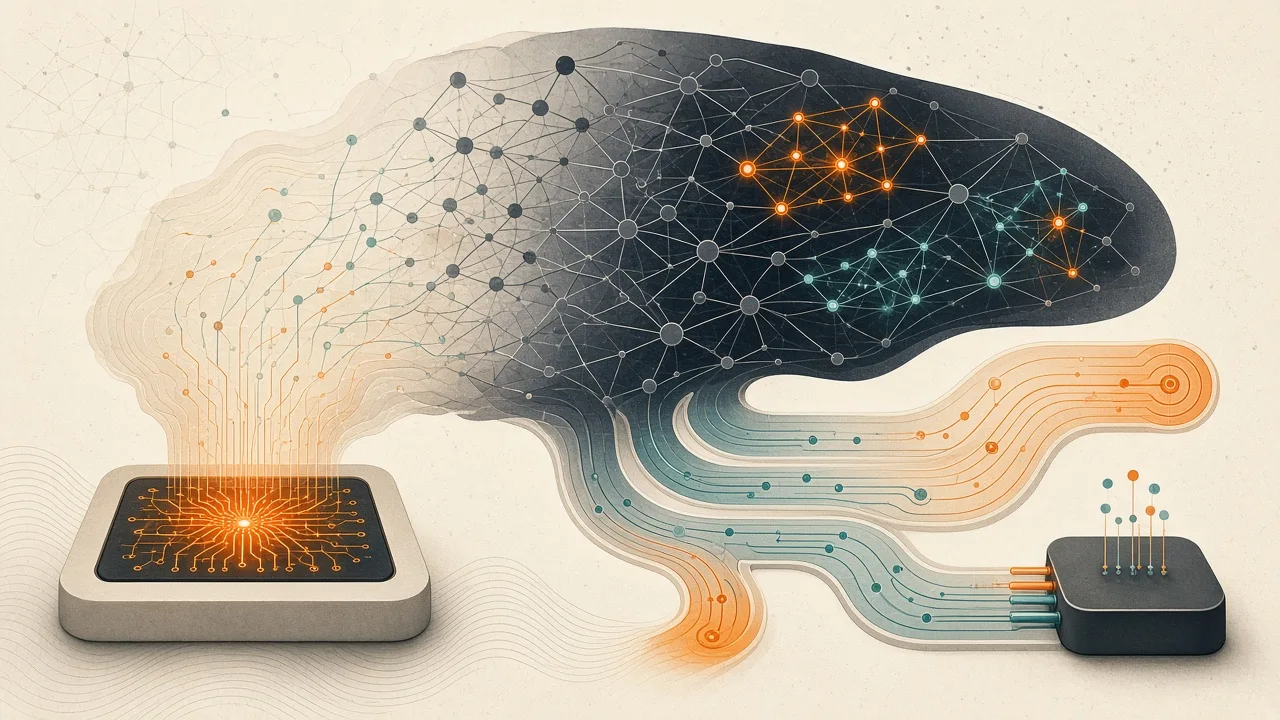
The abstract-only capture from the 2026-10-14 arXiv preprint describes DANGERLENS as a probe that maps hidden states into vocabulary space and applies blinded semantic judgments. This is used to distinguish harmful goals and operational means from hazard recognition and safety control signals.
The authors report experiments on three Qwen1.5 scales comparing paired training histories. Checkpoints previously exposed to harmful content showed greater accessibility of hazardous concepts after the same safety alignment, with the strongest separation observed in intermediate and later layers.
The same harmful update also led to different behavioral trajectories from closely matched starting points. Human relevance validation and readout ablations are mentioned as reinforcing the accessibility contrast.
Evidence Limitations
This report is based solely on the preprint abstract and metadata. Full methodological details, exact experimental setups, quantitative results, and broader applicability remain unknown without the complete paper.
The abstract presents findings on Qwen1.5 models specifically. No independent replication is available, and claims should be treated as preliminary until the full work and potential follow-up studies are reviewed.
Implications for Model Evaluation
The preprint indicates that training history can remain visible in the internal representations of behaviorally matched models. This suggests that refusal behavior alone may not fully capture differences in latent hazardous knowledge.
It argues for considering internal accessibility audits in addition to standard safety benchmarks. Such techniques could help detect traces that might affect future fine-tuning or adversarial interactions, though the precise practicality is not detailed in the abstract.